Pillar guide
Semantic SEO guide
About this guide
I am Daud Lawrence, a Semantic SEO Specialist at Digital Versify, a UK agency in Gravesend. My qualifications are an MBA from the University of Sunderland (2011), an Edexcel Level 7 BTEC (2010), a BA (Hons) in Business Management from Sunderland (2008) and Google Squared Online (2016). More about my background is on my About page.
This page is a reference, not a sales page. It is the parent guide for everything I write about semantic SEO, and shorter articles will sit beneath it and link back here.
Every claim in it carries a numbered reference, so you can check it. I also tag the strength of the evidence, because SEO writing often blurs three very different things:
- Confirmed by Google: Google has said it in its own documentation, blog posts or announcements.
- Inferred: a patent, paper or observed behaviour that suggests something, but does not prove how Google works today.
- Practitioner view: what people in the industry believe or have seen in their own work, including me.
Where I have no source, I say so.
Contents
- About this guide
- What semantic SEO is, and how it differs from keyword-based SEO
- A short history: from strings to things
- How Google understands language: entities, attributes and relationships
- What patents say about entities, and what they do not prove
- Intent and query semantics
- Topical authority: what is known and what is not
- Topical maps: turning a subject into a plan
- Content architecture, silos and structured data: the short version
- Writing semantically: how to make a page clear to people and to search systems
- AI search: what Google says and what is still guesswork
- Semantic SEO for local service businesses in the US and UK
- The method: four stages from research to authority
- Measuring semantic SEO: a Search Console and GA4 plan
- Myths and mistakes in semantic SEO advice
- A semantic SEO checklist
- Glossary
- Frequently asked questions
- Summary
- References
What semantic SEO is, and how it differs from keyword-based SEO
A working definition
Semantic SEO is the practice of making a website’s meaning clear to search systems. It means being clear about which things a site covers, what it says about them, how those things relate to each other, and which questions a visitor is trying to answer.
“Semantic” simply means “relating to meaning”. Search systems do not read a page as a person does. Google has said that its systems try to understand the context of the words in a query, not only the words themselves [5]. Semantic SEO is the work of making your side of that exchange as clear as possible.
An entity is a distinct thing that can be identified and described: a person, an organisation, a place, a product, or an idea. Google describes its Knowledge Graph as something that “understands real-world entities and their relationships to one another: things, not strings” [1]. A string is just a sequence of characters, such as the phrase someone types into a search box.
Semantic SEO is a practitioner label. I have not found the phrase in Google’s documentation, which talks instead about helpful, reliable, people-first content [9]. That does not make the practice invalid, but it does mean no one can claim Google endorses “semantic SEO” as a method.
Keyword-based SEO and semantic SEO side by side
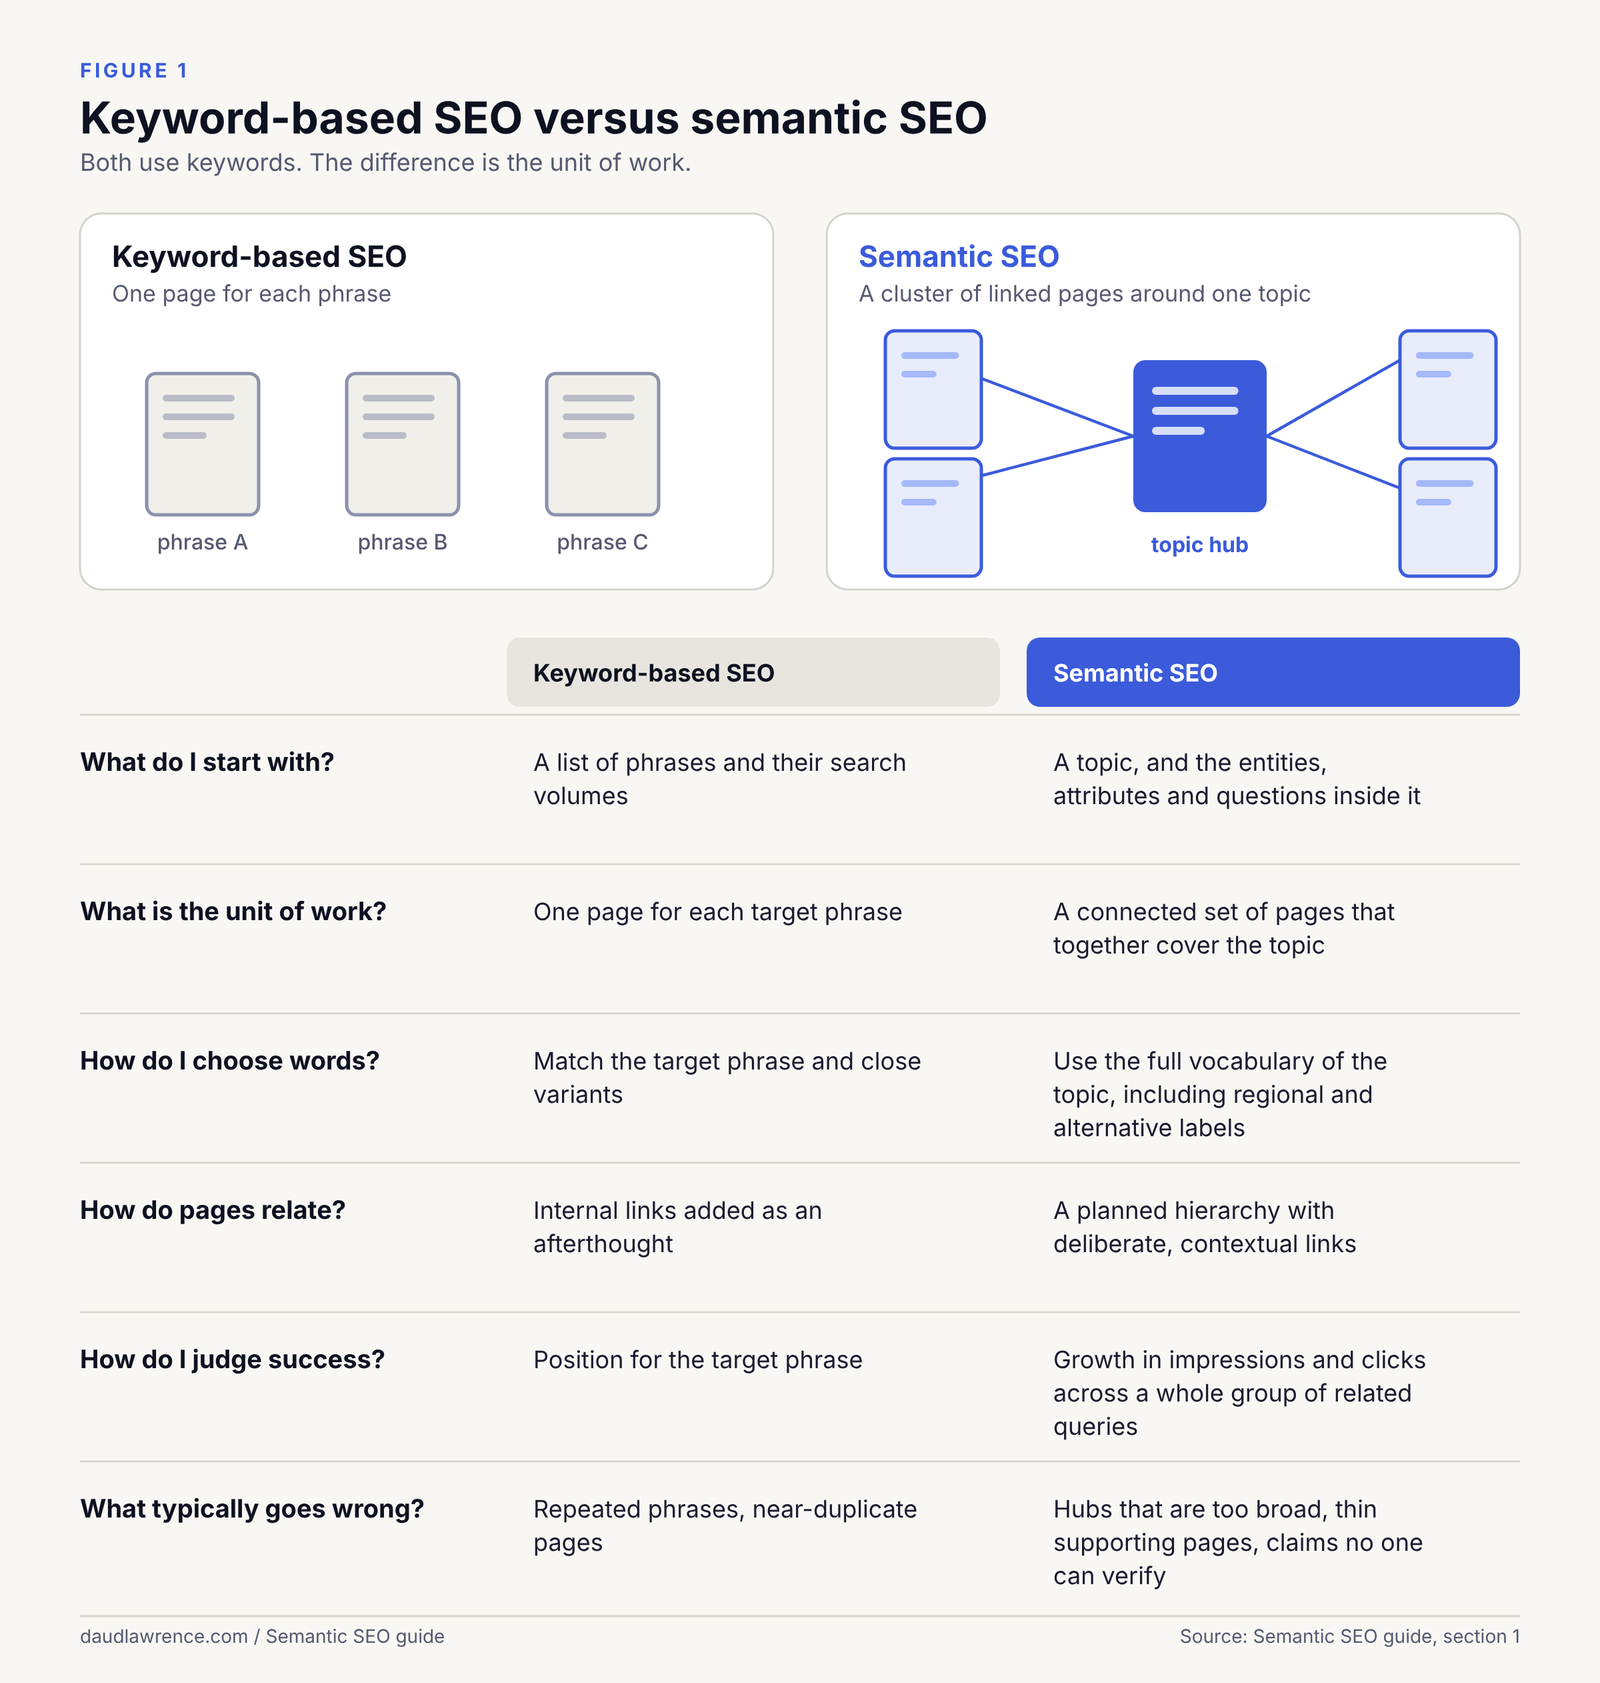
Both approaches use keywords. The difference is what you treat as the unit of work.
| Question | Keyword-based SEO | Semantic SEO |
|---|---|---|
| What do I start with? | A list of phrases and their search volumes | A topic, and the entities, attributes and questions inside it |
| What is the unit of work? | One page for each target phrase | A connected set of pages that together cover the topic |
| How do I choose words? | Match the target phrase and close variants | Use the full vocabulary of the topic, including regional and alternative labels |
| How do pages relate? | Internal links added as an afterthought | A planned hierarchy with deliberate, contextual links |
| How do I judge success? | Position for the target phrase | Growth in impressions and clicks across a whole group of related queries |
| What typically goes wrong? | Repeated phrases, near-duplicate pages | Hubs that are too broad, thin supporting pages, claims no one can verify |
Why this is not a replacement for keywords
Words are still how people search and how pages are matched. When Google disclosed its Hummingbird update in 2013, it said the goal was that “pages matching the meaning do better, rather than pages matching just a few words”, and it also said its advice to publishers had not changed [3]. Meaning is added on top of words. It does not remove them.
An example from two countries
A homeowner in London searching for an “exterminator” and a homeowner in the United States searching for “pest control” want the same service. They use different words for it.
On 20 October 2026 I looked at live Google results for both words from London and from the United States [13]. Three things stood out:
- In London, the results for “exterminator” were mostly pages about pest control. One result was a UK government page titled “Find out about pest control”, and one question shown was “What’s the difference between pest control and an exterminator?” [13]
- In the United States, the top result for “pest control” was a national company whose page title included “Exterminator Service” [13]. The page was written to cover both labels.
- The UK results for “pest control” were led by local firms and directories. The US results included national brands and government and public health pages [13].
This is one snapshot on one day, from two locations, and Google results change. I include it only to show the point: one service entity can have more than one label, and the labels vary by market. A page written for only one label risks being invisible to people who use the other. I return to this in the section on local service businesses.
What semantic SEO does not mean
It does not mean adding schema markup and waiting. It does not mean a secret list of related words. It is not a switch inside Google that you turn on. I deal with these ideas, and with a few popular myths, in the myths section later in this guide.
A short history: from strings to things
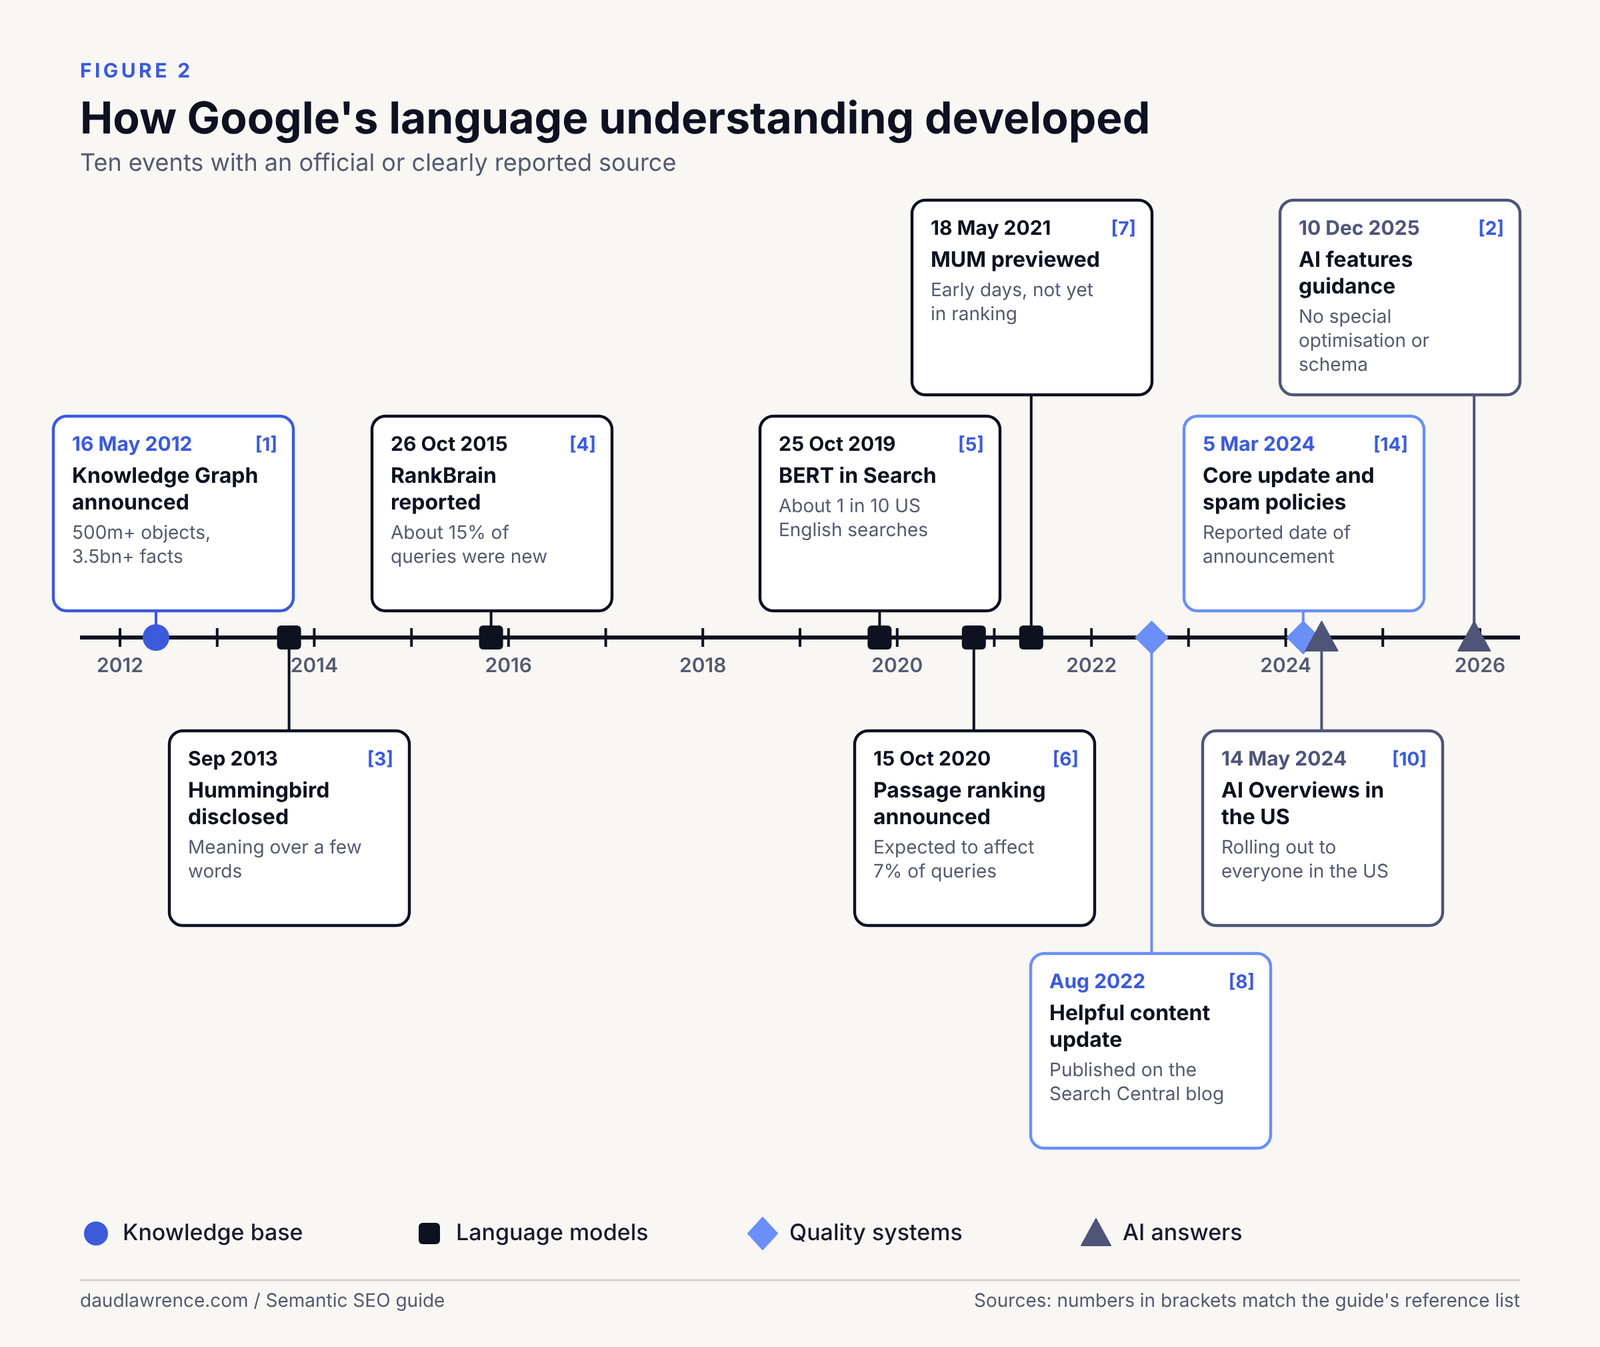
Many guides present Google’s updates as if each one launched “semantic SEO”. Google never described them that way. They were improvements to how Google’s systems understand queries and pages. The practice of semantic SEO is what practitioners built on top of them. The table below lists only events with an official or clearly reported source.
| Date | Event | What was said | Source |
|---|---|---|---|
| 16 May 2012 | Knowledge Graph announced | More than 500 million objects and more than 3.5 billion facts and relationships, drawn from sources including Freebase, Wikipedia and the CIA World Factbook | [1] |
| Late September 2013 | Hummingbird disclosed | Changed about a month earlier; pages matching meaning should do better than pages matching a few words | [3] |
| 26 October 2015 | RankBrain reported | About 15 percent of queries were new to Google; a Google researcher called it the third most important signal | [4] |
| 25 October 2019 | BERT in Search | Helps with about one in 10 searches in US English at launch | [5] |
| 15 October 2020 | Passage ranking announced | Expected to improve 7 percent of queries; BERT used in almost every English query | [6] |
| 18 May 2021 | MUM previewed | Google called it 1,000 times more powerful than BERT; described as early, not yet in ranking | [7] |
| August 2022 | Helpful content update | Published on the Search Central blog | [8] |
| 5 March 2024 | Core update and new spam policies | Reported date of the announcement | [14] |
| 14 May 2024 | AI Overviews | Began rolling out to everyone in the US | [10] |
| 10 December 2025 | AI features guidance updated | No special optimisation or schema needed | [2] |
What each step changed, and what it did not
The Knowledge Graph was about organising facts, so that Google could answer questions about things directly [1]. Hummingbird, RankBrain and BERT were about reading queries better, especially long, new or conversational ones [3][4][5]. Google’s BERT example is useful here: in the query “2019 brazil traveler to usa need a visa”, the word “to” decides who is travelling where, and BERT helps Search read that [5].
Passage ranking let Google judge a section of a page, rather than only the whole page, for certain queries [6]. MUM was presented as a larger model that handles many languages and more than one type of content [7]. Google said at the time that it was early days [7].
The helpful content update and the people-first guidance shifted attention to quality and trust. Google’s current guidance says E-E-A-T, meaning experience, expertise, authoritativeness and trustworthiness, “isn’t a specific ranking factor”, and that trust is the most important part [9].
What this history does not prove
Be careful with the numbers. The 15 percent figure and the “third most important signal” comment from 2015 are reported statements from one moment in time [4]. I treat them as history, not as a current ranking weight. The “1,000 times more powerful” line for MUM is Google’s own description of its model, not an independent test [7].
Nothing in the table proves that any single tactic, such as covering a topic in depth or adding entities to your copy, will improve rankings. That evidence comes from patents, papers and practitioners, and I treat it separately in later sections.
How Google understands language: entities, attributes and relationships
The building blocks
Search systems describe the world as entities, the attributes that describe them, and the relationships that link them. This is easier to see with an example. The business below is made up, to avoid pointing at a real company.
Northgate Commercial Cleaning Ltd (illustrative only)
- Entity type: a company that provides a service.
- Attributes: legal name, address, service area, the services it offers, opening hours.
- Relationships: located in a city, serves a type of customer (offices, schools), belongs to a trade body, is run by a named person.
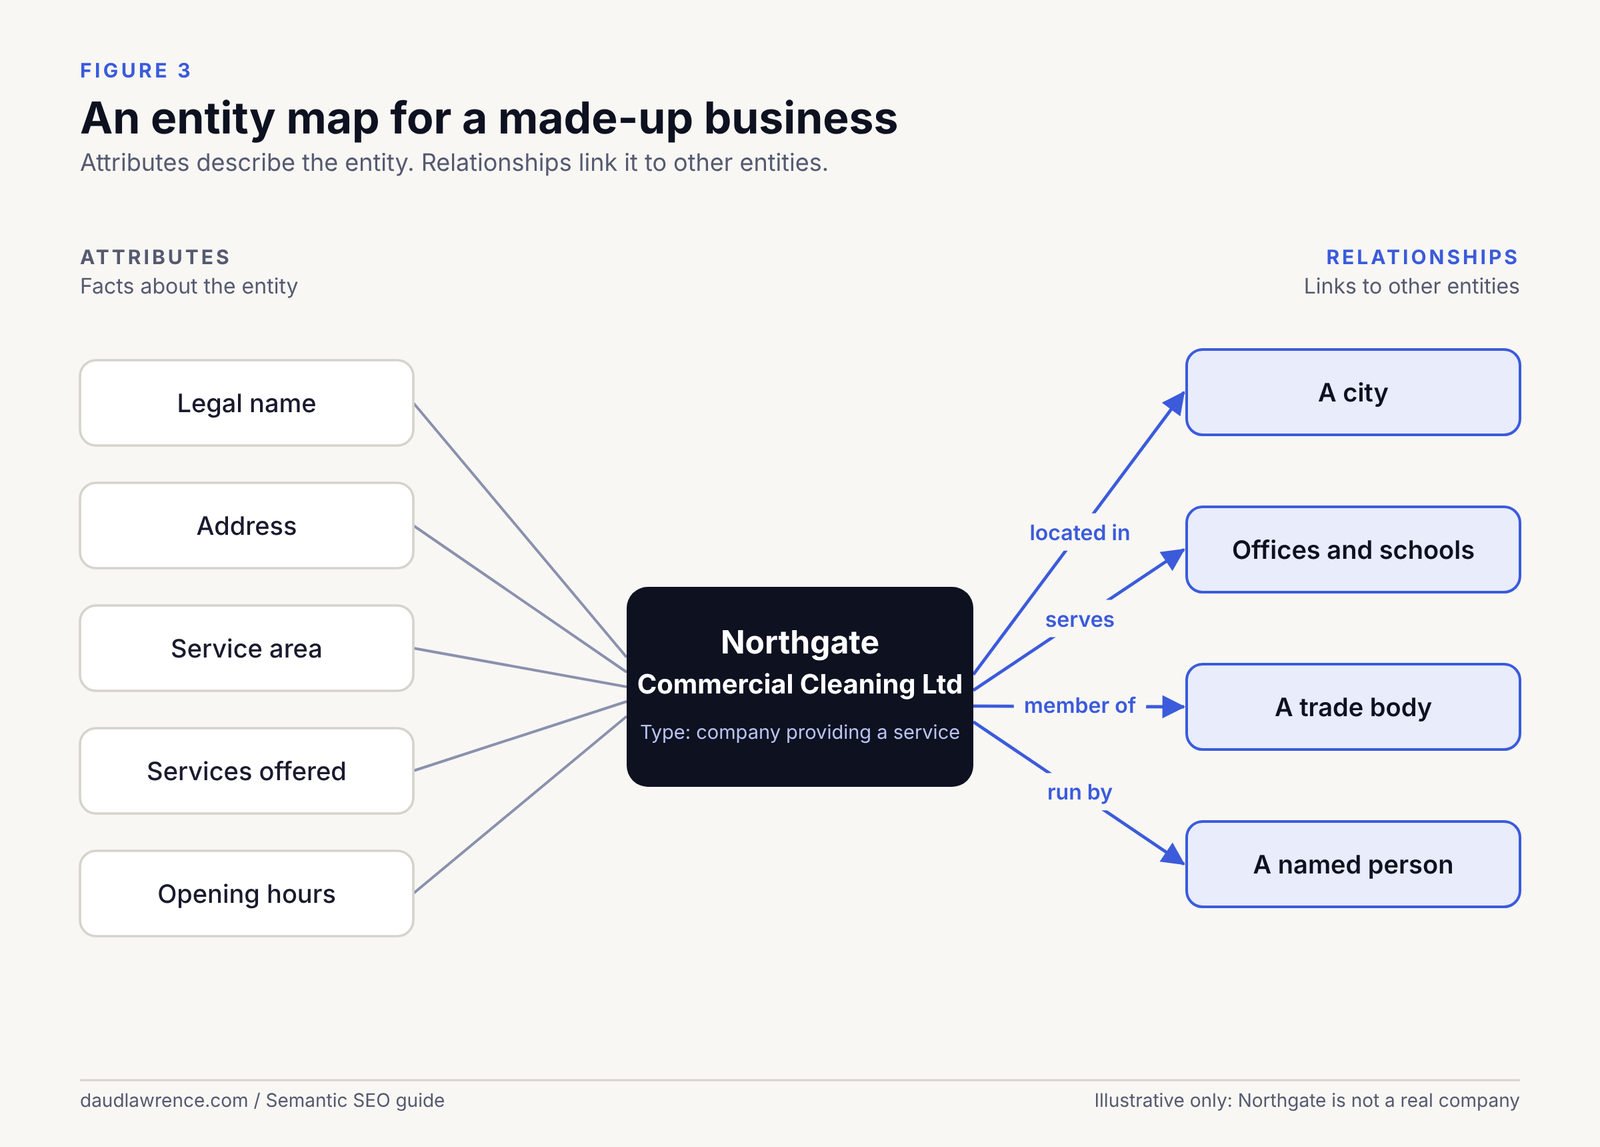
This is the model behind a Knowledge Graph: things, facts about them, and links between them [1]. A page that states these facts clearly gives a search system more to work with than a page that only repeats a phrase.
What the Knowledge Graph is, and what we can check
In 2012 Google said the Knowledge Graph held more than 500 million objects and more than 3.5 billion facts and relationships [1]. It named Freebase, Wikipedia and the CIA World Factbook as sources, and said it was tuned by what people search for and what it finds on the web [1].
You can query a small public window onto it. Google’s Knowledge Graph Search API returns individual entities, using schema.org types, with identifiers such as kg:/m/0dl567[11]. The documentation also sets limits: it is read-only, it “is not suitable for use as a production-critical service”, and it returns individual entities rather than graphs of connected ones [11]. I have not found a current Google document that lists all the sources of the Knowledge Graph today.
Entity reconciliation
Entity reconciliation means deciding that different mentions refer to the same thing. “D. Lawrence”, “Daud Lawrence” and a profile photo on two sites might all describe one person. Or they might describe three. A system that cannot tell will treat them as separate, or will ignore them.
Reconciliation is a term from data integration. I have not found a Google document that describes how Google does this for the open web, so what follows is an inference. Consistent names, consistent descriptions, and links between your own site and your profiles elsewhere give a system more evidence that the mentions belong together. That is why I say the aim of a site such as mine is to be a clear, verifiable source about its own subject.
Reconciliation also works the other way. A word can point to more than one entity. In the UK, “skip” is mostly a waste container hired for building work. Its context words are things like yard sizes, delivery and permits. A system reads those surrounding words to choose the right sense, which is the same kind of context reading Google described for BERT [5].
Co-occurrence and co-citation
Co-occurrence means two terms or entities appearing close together in text. If a page about commercial cleaning mentions waste disposal, health and safety and contract length alongside it, those terms co-occur with the main subject. Co-citation is an older idea from information science: two documents are related when a third document cites both. Henry Small described it in 1973 for scientific papers [12].
Practitioners often apply both ideas to the web. They say that being mentioned alongside respected sources, and covering the terms that normally appear around a subject, helps a system place you. That is a practitioner view and an inference. Small’s paper is about scientific literature, and I have not found a Google statement that confirms co-citation works this way in web ranking. The next sections look at patents that touch related ideas, and I will be explicit about what they do and do not show.
Where to go for the deeper version
This section gives the model. Stating entities in structured data and in site architecture is covered in depth in my second pillar guide, Content architecture for topical authority.
What patents say about entities, and what they do not prove
How I read a patent
A patent is a legal document. It describes an idea an inventor wants to protect. It does not say the idea is in use, and a granted patent may never ship. Several guides quote patents as if they were Google’s current rulebook. I do not, so each patent below is tagged Inferred.
For each one I give the filing and grant dates, say what the description is about, and then say what I can and cannot conclude. I read the title, abstract, summary and description on each Google Patents page. I did not read the claims, which define the legal scope, so I do not describe what each patent protects. All four were originally filed by Google Inc., now Google LLC.
Four patents worth knowing
| Patent | Filed | Granted | What the description covers |
|---|---|---|---|
| US10235423B2, “Ranking search results based on entity metrics” [18] | 12 December 2012 | 19 March 2019 | Computing several metrics for each result, weighting them by the type of entity in the search, combining them into a score and ranking by that score |
| US9336311B1, “Determining the relevancy of entities” [19] | 15 October 2012 | 10 May 2016 | Finding entities related to the entity in a query, scoring them by popularity and freshness, and returning those above a threshold, for example in an answer box |
| US9256682B1, “Providing search results based on sorted properties” [20] | 5 December 2012 | 9 February 2016 | Scoring related entities against each property of an entity, combining the scores per property, and sorting the properties for each entity type |
| US9213745B1, “Methods, systems, and media for ranking content items using topics” [21] | 15 March 2013 | 15 December 2015 | Checking whether search results contain entity types tied to a content class, such as movies, and promoting that class if the query appears to be seeking it |
What each one suggests
Entity type changes how results are weighted. The 2012 filing on entity metrics describes weighting ranking signals differently depending on the type of entity involved [18]. The idea is intuitive: what makes a good result for a film is not what makes a good result for a plumber. For a practitioner, the lesson is to be clear about which type of entity a page is about.
Related entities can be scored for relevance. The relevancy patent describes starting from the entity in a query, finding related entities through a knowledge graph, and scoring them by popularity and freshness [19]. The examples given include signals such as query volume and dates. The description presents these as embodiments, so I cannot say they are required.
Properties can be ranked within an entity type. The sorted properties patent describes deciding which attributes of an entity matter most for its type [20]. It supports a modest idea: some attributes of a thing are more important than others, and a page that covers the important ones first is easier to use.
Entity types in results can reveal what a query wants. The content items patent is the narrowest. Its abstract is about video content, and about inferring that a query is seeking a class such as movies by looking at the entity types in the results [21]. I include it because it shows the same pattern of reasoning about intent, not because it describes ordinary web page ranking.
What none of this proves
Four patents filed within about a year of each other show that Google was working on entity-based ideas in 2012 and 2013. They do not show how Google ranks pages today. None of them, in the parts I read, describes a score for a website’s overall authority on a topic. None says a page ranks better because it names more entities.
The honest summary is this: the patents support the idea that entities, entity types and attributes matter to search systems. They do not support any specific tactic, such as a target number of entities per page. When a guide says “Google’s patent says to do X”, ask which patent, which claim, and whether the claim describes a live system.
Intent and query semantics
What Google says about intent
Google’s rater guidelines are the closest public description of how Google thinks about what a query wants. They are written for the people Google hires to rate search quality, not for publishers. The version I read is dated November 2023 [16]. A newer version may exist.
The guidelines say a rater should first work out the intent of the query, using the query and, where relevant, the user’s location [16]. Two of their examples are useful. A search for “coffee shops” in London is a request for nearby places. A search for “mercury” could mean the planet or the chemical element [16]. Results are then rated on how well they meet the need, on a scale from “Fails to Meet” to “Fully Meets” [16].
Two cautions apply. The guidelines state that quality ratings on their own do not directly affect how a particular page appears in Search, and are used to measure how well the systems perform [16]. And I did not find a fixed list of intent types in the version I read, so I do not present one as Google’s.
Google’s own explanation of how Search works adds that relevance depends on many factors, including location, language and device, and that the wording of a query changes the features shown [22]. Its examples are a query like “modern bicycle”, which is more likely to show images, and “bicycle repair shops”, which tends to show local results [22].
What the live results show
You can read intent from what Google actually returns. On 20 October 2026 I compared results for the same service in the UK and the US [13]:
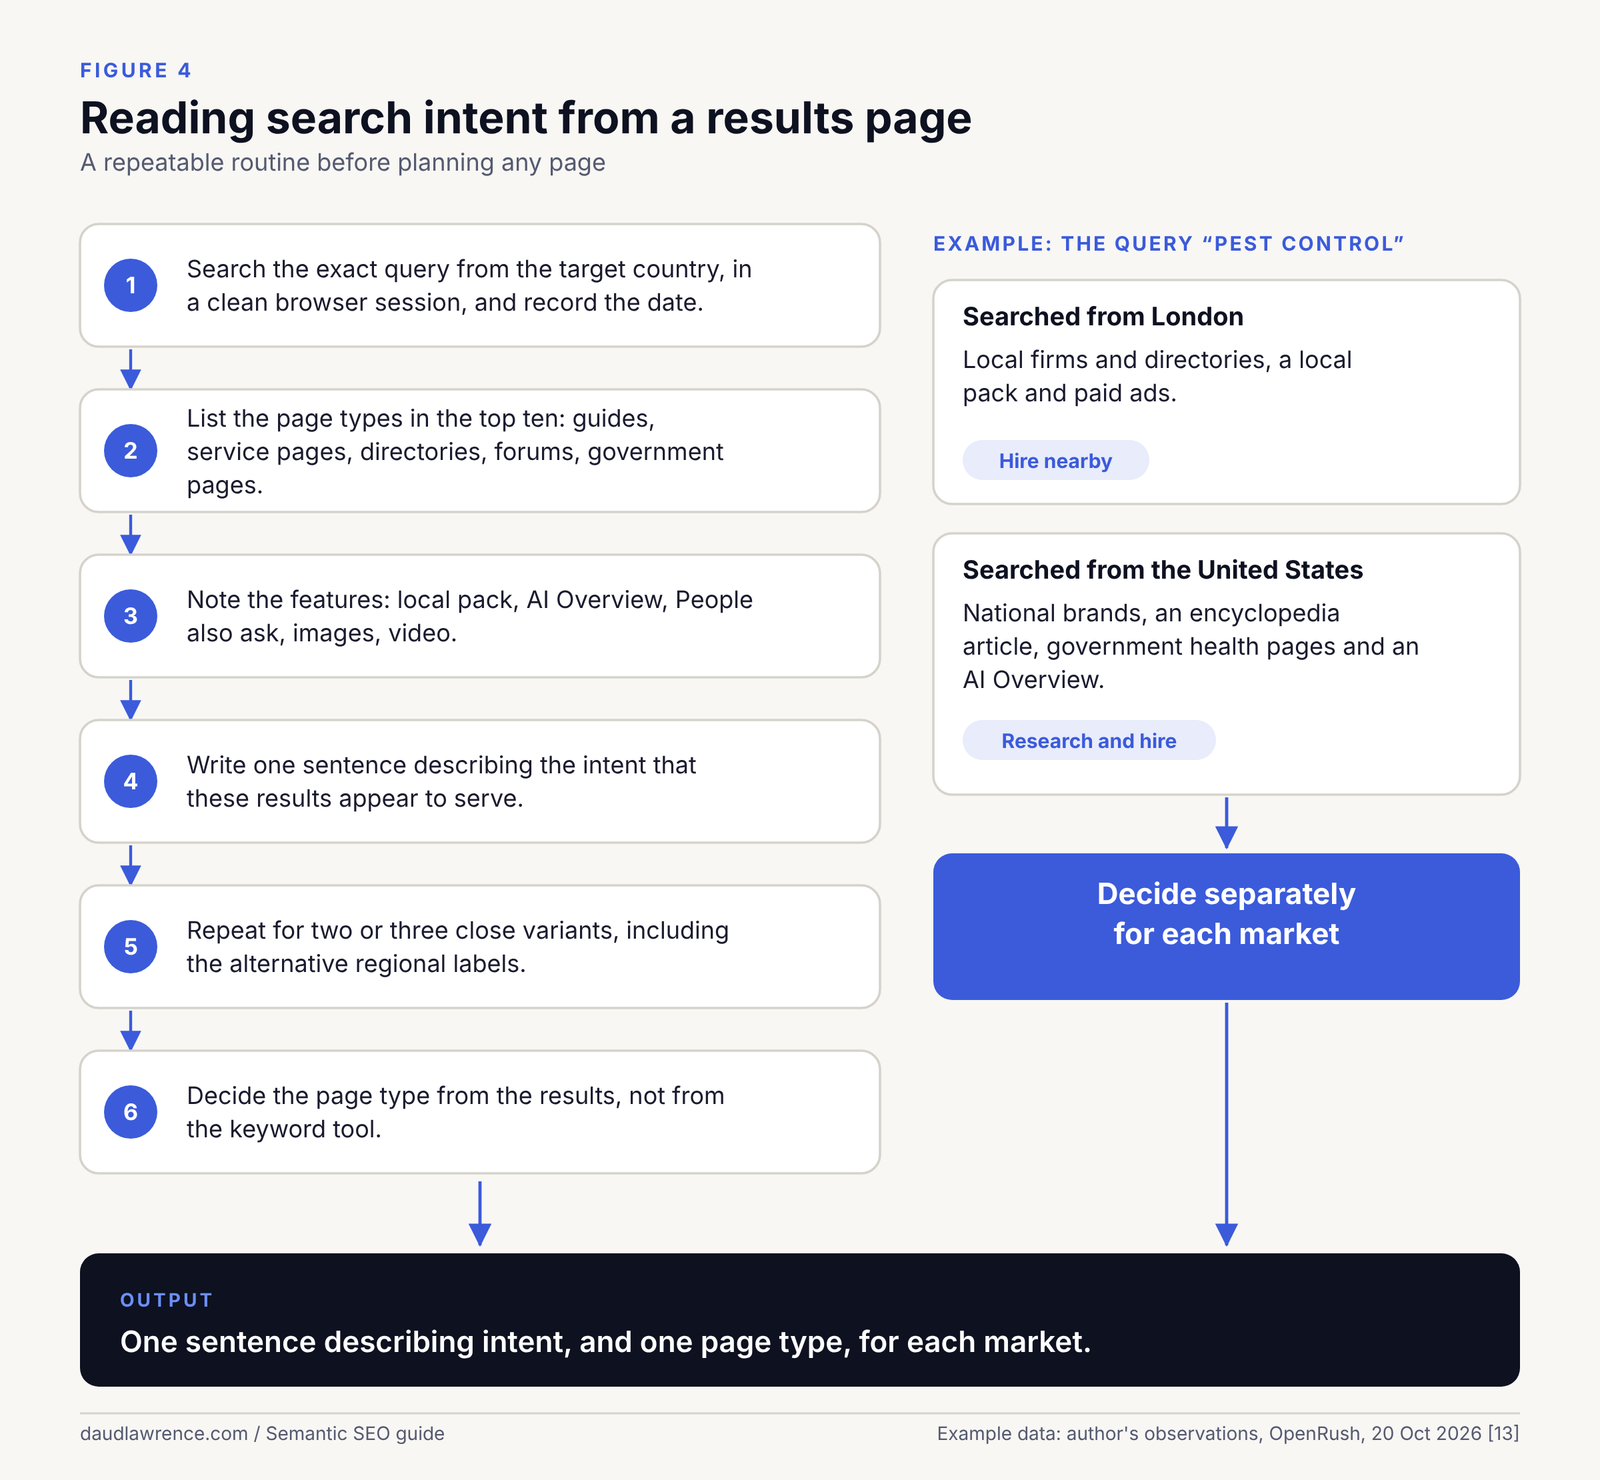
- “Pest control” from London returned mostly local firms and directories, with a local pack and paid ads.
- “Pest control” from the United States returned national brands, an encyclopedia article and government health pages, with an AI Overview.
Same service, same language, different result types. Google appears to treat the UK query as a request to hire someone nearby, and the US query as a broader mix of research and hiring. That is an observation from one snapshot [13], not a rule. It does show why I check the live results in the target country before I decide what a page should be.
A working scheme for intent
Practitioners usually sort queries into informational, commercial investigation, transactional and local or navigational. This is a practitioner view. It is a useful way to plan, but it is not a Google taxonomy. I use it as a first pass and then let the results overrule it.
| Working type | What the searcher wants | What the page usually looks like |
|---|---|---|
| Informational | To understand something | Guide, definition, explainer |
| Commercial investigation | To compare options | Comparison, checklist, buying guide |
| Transactional | To do or buy something | Service or product page |
| Local | A provider near them | Location page, listing, local pack |
Reading a results page, step by step
This is the routine I follow before planning any page.
- Search the exact query from the target country, in a clean browser session, and record the date.
- List the page types in the top ten: guides, service pages, directories, forums, government pages.
- Note the features: local pack, AI Overview, “People also ask”, images, video.
- Write one sentence describing the intent that these results appear to serve.
- Repeat for two or three close variants, including the alternative regional labels.
- Decide the page type from the results, not from the keyword tool.
Queries are now broken into parts
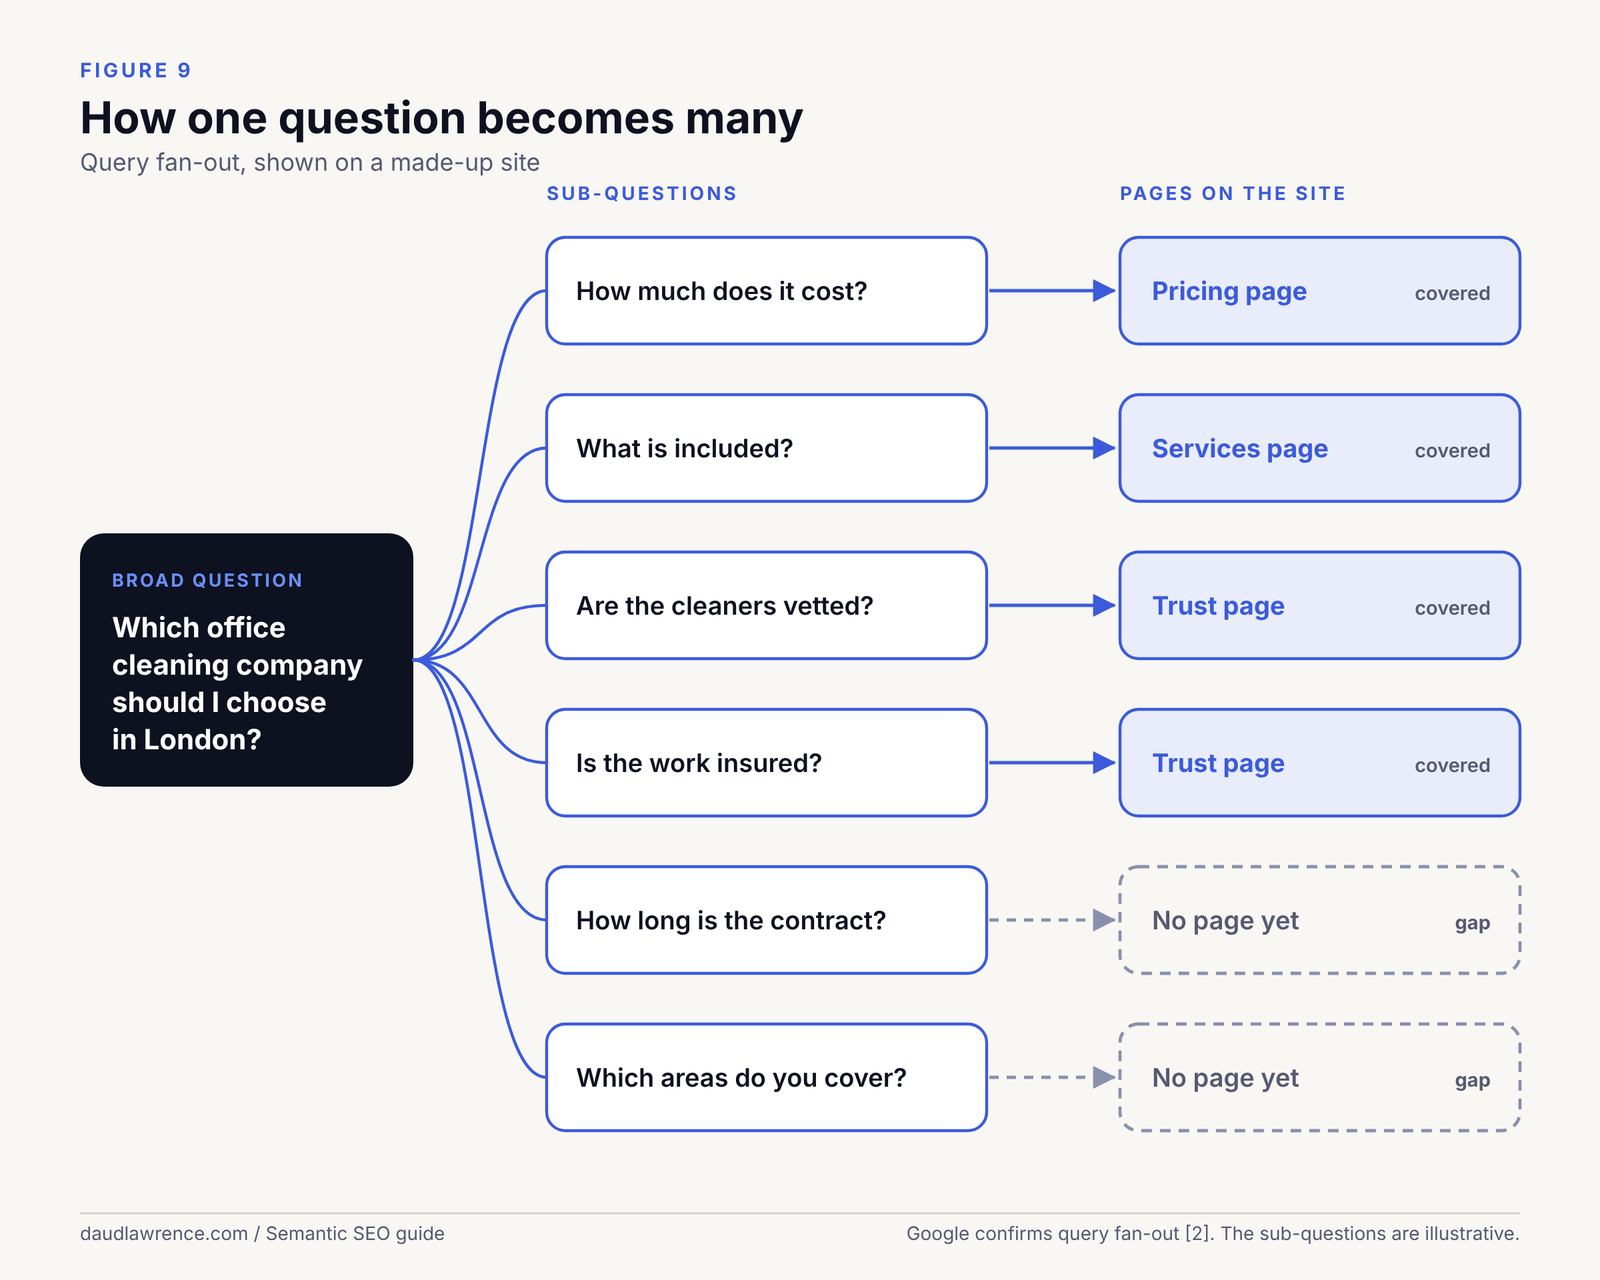
Google has described a technique called query fan-out. In May 2025 Elizabeth Reid said AI Mode uses it to break a question into subtopics and run many searches at once, and that Deep Search takes the same approach further, issuing hundreds of searches to produce a cited report [17]. I read that as confirmation that one question can become many.
That is confirmed for AI Mode. It does not tell us which subtopics Google chooses, or how pages are picked for each. What I take from it is practical, and it is an inference: a page or a site that covers the likely sub-questions of a topic clearly gives a system more to retrieve.
Topical authority: what is known and what is not
The term and where it comes from
Topical authority is a practitioner term. It describes the idea that a site which covers a subject thoroughly, accurately and consistently becomes a more trusted source on it, and that this helps its pages rank across the subject. I have not found the phrase in Google’s search documentation.
What Google has said
Google has not published a topical authority score. In a Reddit discussion in 2023, John Mueller of Google replied “Don’t worry about it” to a thread questioning the term, according to a Search Engine Journal report [15]. The same report quotes its author arguing that there is no actual authority score at Google [15]. I treat both as indirect evidence. The Reddit comments are undated in the article, and the report is a secondary source.
Google’s published guidance on helpful content says to create content for people, show first-hand experience and expertise, and be clear about who wrote it and why [9]. It also says E-E-A-T “isn’t a specific ranking factor”, while trust is the most important part of it [9]. This is relevant, because those qualities are what a site with real depth would show.
Why the idea is still useful
There is no confirmed score, but the underlying practice has reasons behind it that I can defend:
- Readers who find a clear answer often want the next one. A site that already has it serves them better.
- Google can judge parts of a page, not only the whole page, which makes well-organised sections valuable [6].
- Entity-based patents suggest that systems weigh related entities and attributes, so complete coverage of a subject is easier to place [18][19][20].
- A site that links related pages sensibly makes it easier for a crawler and a reader to find them. I cover this later, and in more depth in my content architecture guide.
Each of these is an Inference or Practitioner view. Together they justify planning around topics. They do not justify claiming that topical authority is a ranking factor.
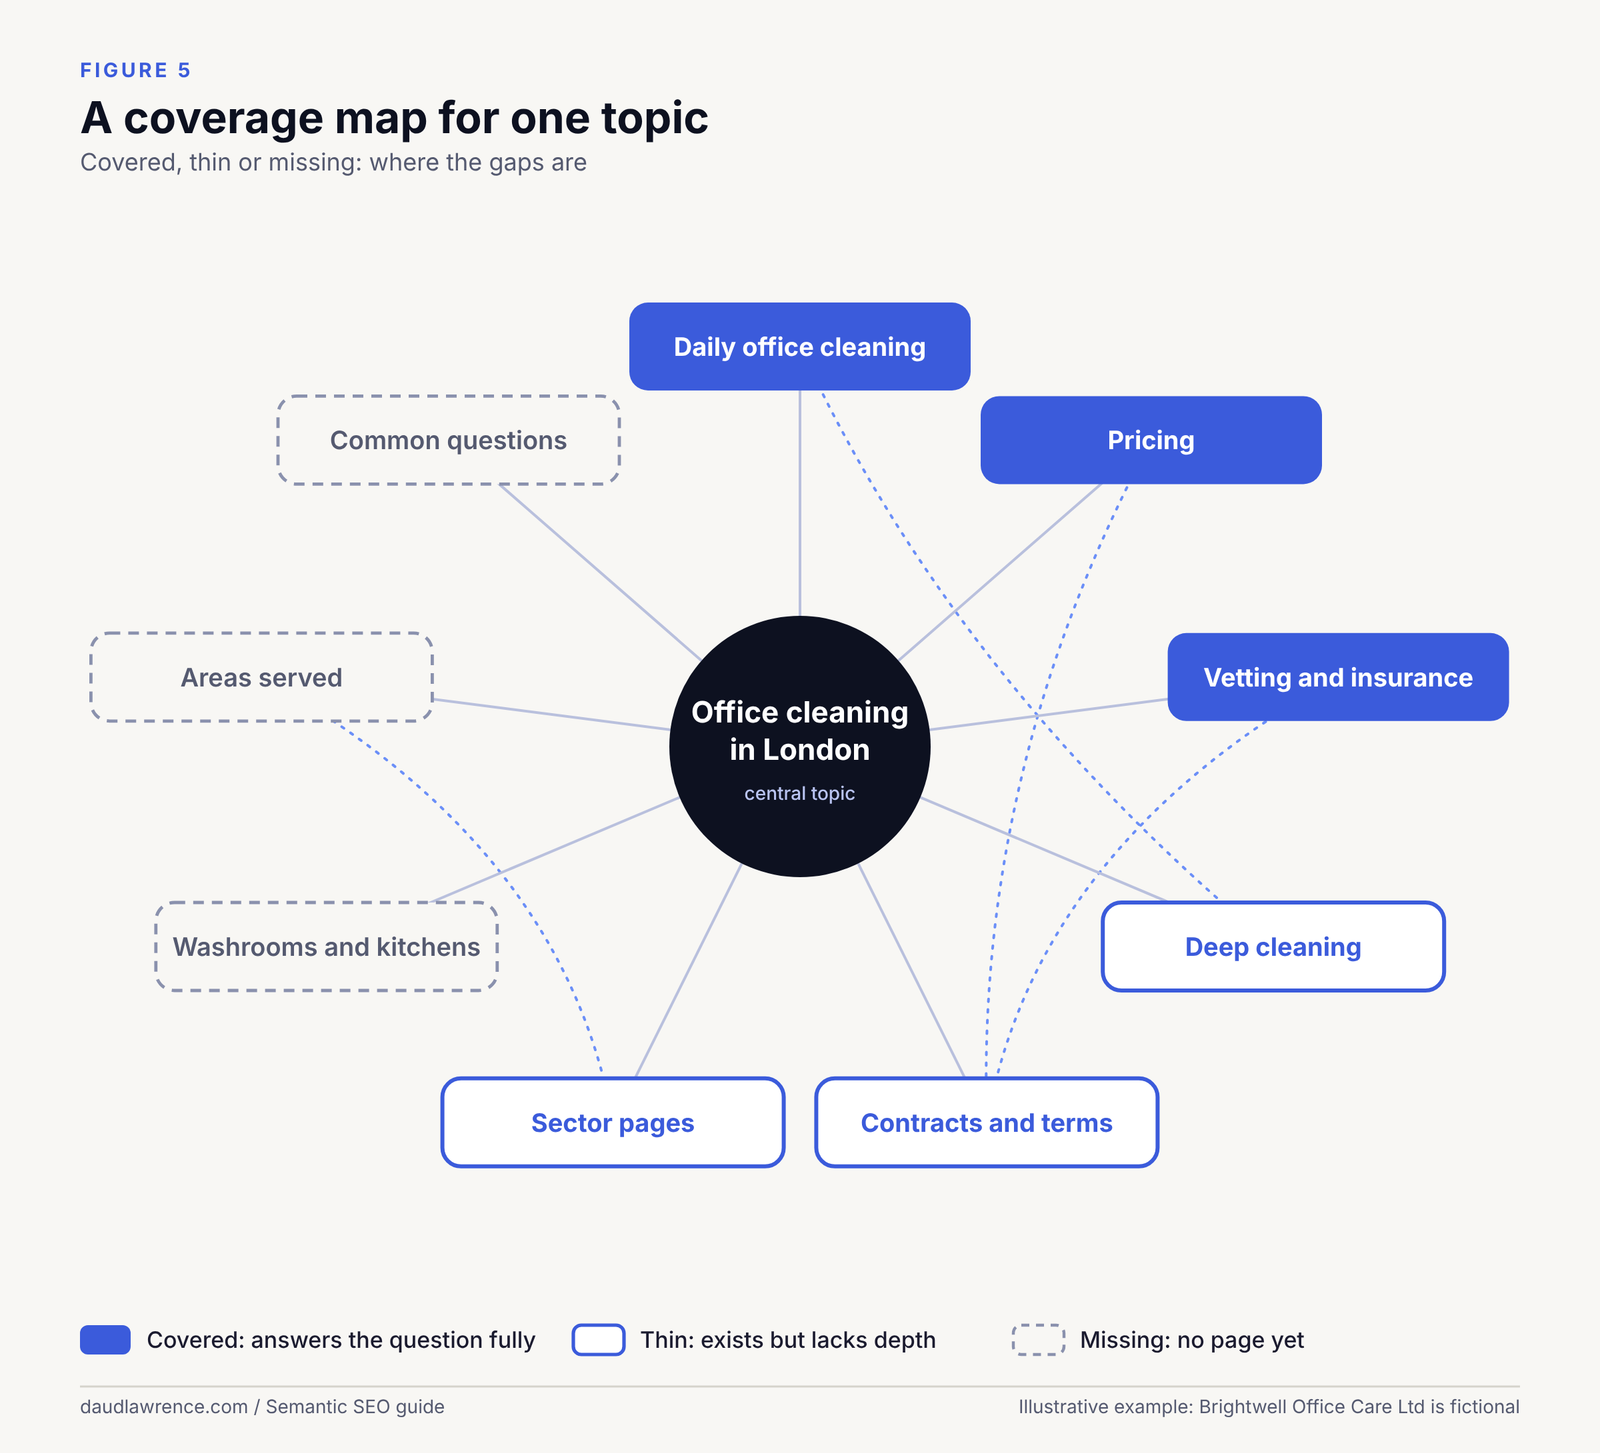
How I judge whether coverage is good enough
I use four checks. They are my own working tests, not Google criteria.
| Check | Question | Evidence to look at |
|---|---|---|
| Breadth | Does the site cover the main sub-topics a searcher would expect? | A list of sub-topics built from live results and “People also ask” |
| Depth | Does each page answer its question fully, with specifics? | Whether a reader could act on the page without searching again |
| Consistency | Do pages use the same names and facts for the same things? | Names, definitions and figures compared across pages |
| Evidence | Can claims be checked? | Sources, named authors, dates |
Treat it as a hypothesis, then measure it
Because the evidence is indirect, I treat topical authority as a testable hypothesis. For example: “If I publish the six missing supporting pages for this cluster, impressions for the cluster’s queries in the target country will rise within three months.” I record the starting position, publish, and measure by country and cluster in Search Console. If the numbers do not move, the hypothesis has failed, and that is useful to know. I give the measurement approach in a later section.
Topical maps: turning a subject into a plan
What a topical map is
A topical map is a planned list of the pages a site needs to cover a subject, with the purpose of each page, the questions it answers and how it links to the others. It is a practitioner tool. Google does not mention topical maps in its documentation, so I treat the method as a way of organising work, not as a ranking technique.
A map is useful because it shows gaps and duplicates before anything is written. It also gives each page a single job, which makes it easier to judge later whether the page worked.
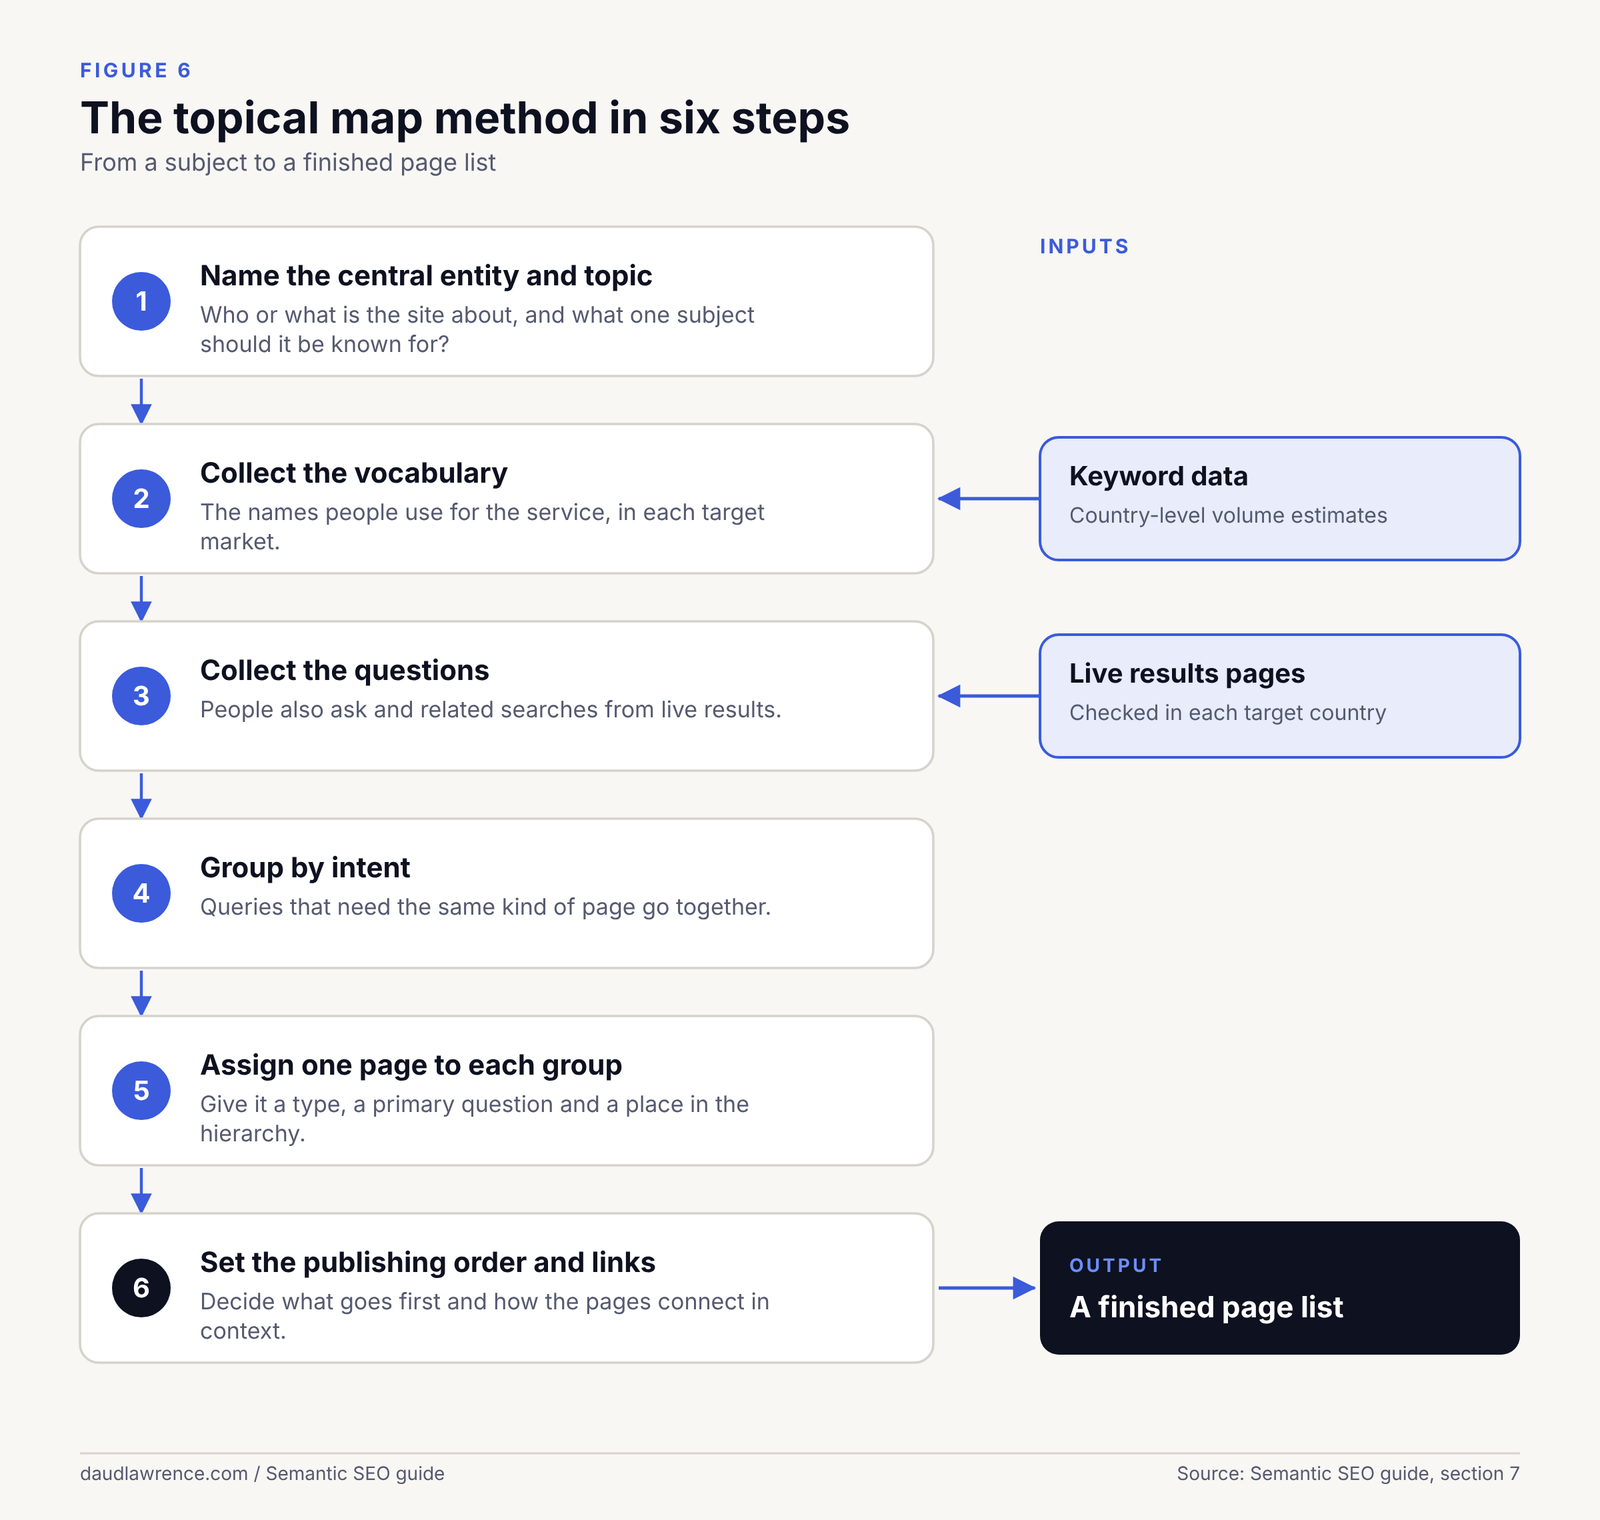
The method I use
- Name the central entity and the central topic. Who or what is the site about, and what is the one subject it wants to be known for?
- Collect the vocabulary. Gather the names people use for the service, in each target market, from live results and keyword data.
- Collect the questions. Use “People also ask” and related searches from the live results page, not only a keyword tool.
- Group by intent. Put queries that need the same kind of page together, and separate those that need different pages.
- Assign one page to each group. Give it a type (hub, service, guide, location), a primary question and a place in the hierarchy.
- Set the publishing order and the links. I explain how in the next sections.
How to read the data in the examples
The next two sections use search data. Before you read the figures, five cautions apply.
- All volumes come from OpenRush keyword research, run on 20 October 2026, and are monthly estimates at country level [24]. The tool does not give city volumes, so a figure for “office cleaning london” is the number of searches in the whole United Kingdom that contain those words.
- Volumes are rounded by the tool, and several word-order variants of one phrase can share one number. In the US data, six re-orderings of “commercial cleaning services” all showed 90,500 [24]. Do not add such variants together.
- Estimates are not Search Console data. Only your own account shows what your site actually received.
- Intent labels in the tool are automated. Searches for jobs, for example, are mixed in with searches for services in both countries [24].
- The result pages are single snapshots taken at the same time as the keyword data [13].
Two fictional businesses
Both businesses below are invented for this guide. They do not exist, and I have not matched the names to any company register. If a real firm has a similar name, it is a coincidence. Their purpose is to show a method, not to describe any real company.
- Brightwell Office Care Ltd is an imaginary commercial cleaning company based in London.
- Prairie Line Janitorial LLC is an imaginary commercial cleaning company based in Chicago.
Both do the same job: they clean offices and other commercial buildings on a contract. I chose these two cities because the live results tool could return city-level results for both, and because both city names appear in the keyword data.
Worked example A: London
Central entity: Brightwell Office Care Ltd, a limited company that provides office cleaning in London.
Vocabulary. In the UK data, the service has several labels (see the table below). “Office cleaning” and “commercial cleaning” are the most useful. “Janitorial” does not appear among the top UK suggestions I pulled [24].
| Query (UK) | Estimated monthly searches | Note |
|---|---|---|
| commercial cleaning | 2,900 | Broad; mixes domestic and business results |
| london office cleaning | 2,400 | Location in front |
| office cleaning company london | 2,400 | Company-seeking wording |
| office cleaning london | 1,900 | The closest match to the service page |
| commercial cleaning services | 1,900 | Broad service label |
| commercial cleaning services london | 1,300 | Business-to-business |
| commercial cleaning services near me | 1,000 | Local intent without a place name |
| commercial cleaning services birmingham | 480 | Shows how fast volume falls outside London |
| commercial cleaning services manchester | 70 | Very low |
| commercial cleaning services prices | 140 | Low volume, high commercial intent |
Source for all rows: OpenRush keyword research, 20 October 2026 [24].
Two things stand out. London carries most of the local demand in the data. And a jobs query, “office cleaning jobs”, sits at 1,600 searches [24], so a page that is not clear about whether it hires staff or supplies a service can attract the wrong visitors.
What the live results show. On 20 October 2026, nine of the top ten results for “office cleaning london” from London were company websites, and one was Checkatrade’s directory page. There was a local pack of three businesses with 25 to 50 reviews each, and no AI Overview [13]. People also ask included “How much does office cleaning cost in London?” and “What is included in office cleaning?” [13]. Snippets in the results mention vetted cleaners, DBS checks and COSHH compliance [13]. These are the trust signals UK competitors choose to state.
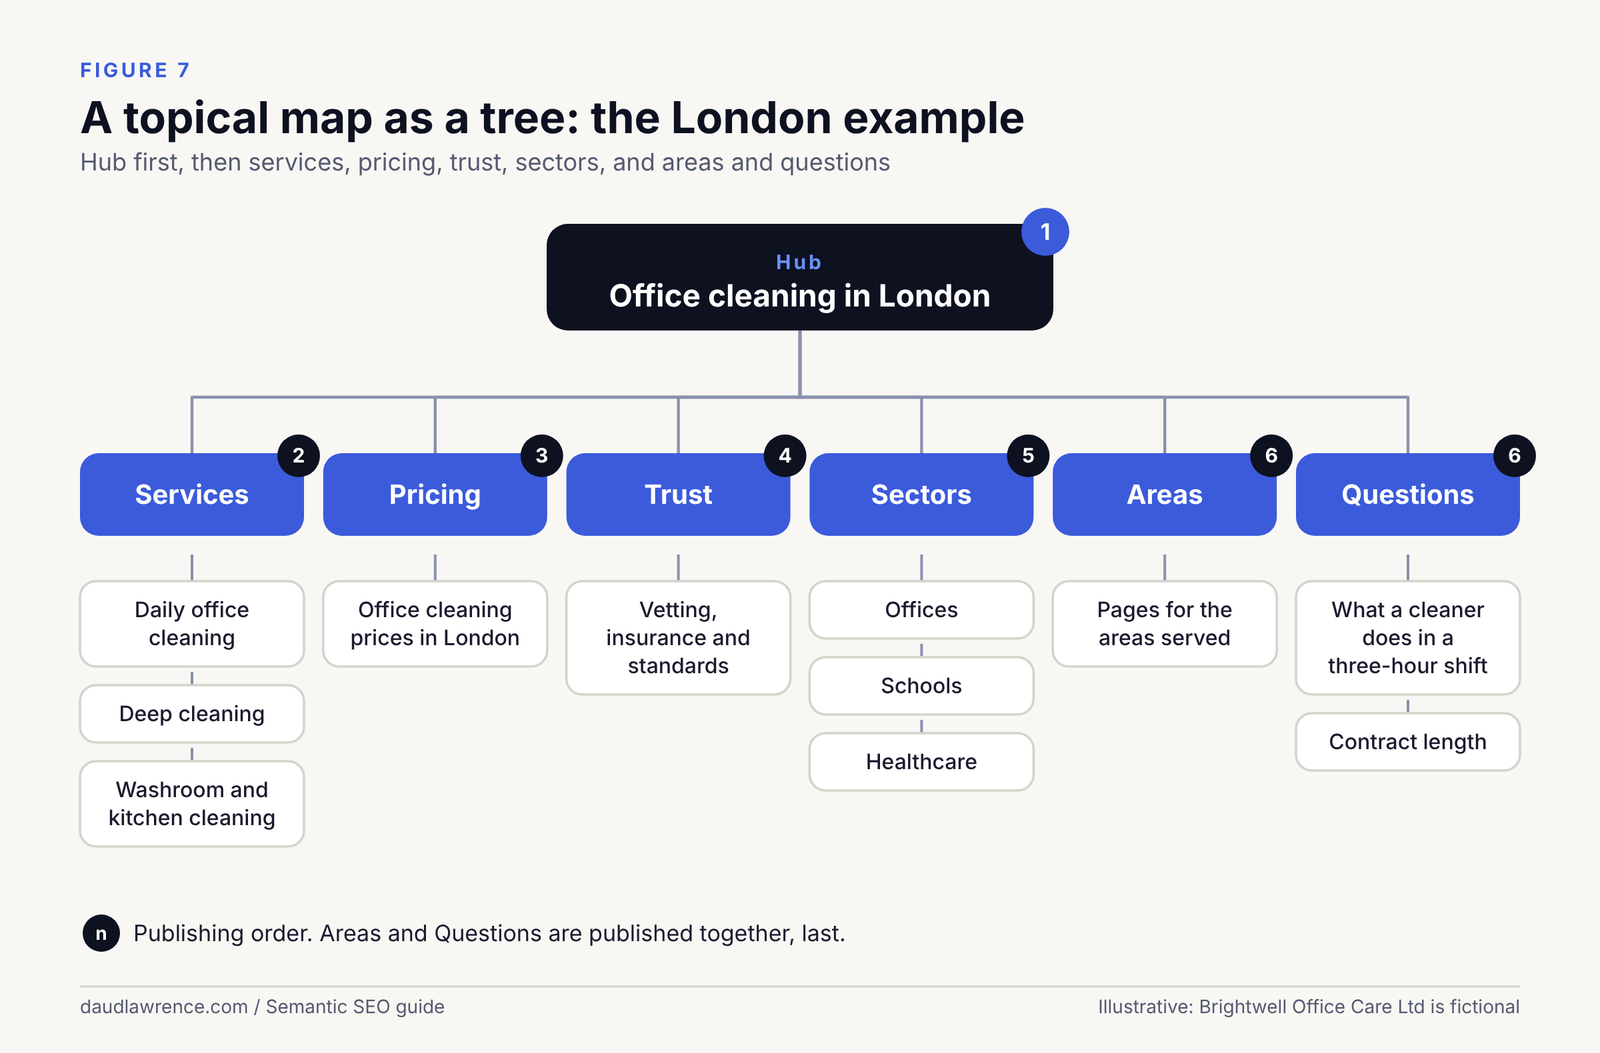
The map for Brightwell.
| Cluster | Page | Primary question | Intent |
|---|---|---|---|
| Hub | Office cleaning in London | What does an office cleaning contract involve? | Commercial |
| Services | Daily office cleaning; deep cleaning; washroom and kitchen cleaning | What is included, and how often? | Commercial |
| Pricing | Office cleaning prices in London | How much does it cost? | Commercial investigation |
| Sectors | Cleaning for offices; for schools; for healthcare | What does my type of building need? | Commercial |
| Trust | Vetting, insurance and standards | Can I trust the people in my building? | Commercial investigation |
| Areas | Pages for the specific parts of London served | Do you cover my postcode? | Local |
| Questions | What a cleaner does in a three-hour shift; contract length | A practical, specific question | Informational |
The question “What will a cleaner do in 3 hours?” is taken directly from the live “People also ask” box [13]. A question like that is often not served well by the generic pages that dominate the results, so it is a place to add something original.
Publishing order. Hub first, then the three or four services, then pricing, then trust, then sectors, then areas and questions. The reason is dependency: every later page links up to the hub and sideways to services, and the hub is only credible once the pages it summarises exist. This is an inference from how I structure sites, not a Google rule.
Local signals for the UK example. A Google Business Profile, a consistent name and address across the site and directories, and a listing on directories that appear in the results such as Checkatrade [13]. A UK limited company also has a public record at Companies House, which is a place where the business name and address should match the site [31]. The BICSc, the British Institute of Cleaning Science, describes itself as “the largest independent, professional and educational body within the cleaning industry” and offers membership and accredited training [29]. Membership is a fact a business can state if it is true, and it is a verifiable relationship to an organisation outside the site.
Worked example B: Chicago
Central entity: Prairie Line Janitorial LLC, a limited liability company that provides commercial cleaning and janitorial services in Chicago.
Vocabulary. The US data is much larger, and the service label shifts. “Janitorial services” appears as a major head term, alongside “commercial cleaning services” [24].
| Query (US) | Estimated monthly searches | Note |
|---|---|---|
| commercial cleaning services | 90,500 | Broad; many re-orderings share this figure |
| janitorial services | 27,100 | The US label for the service |
| commercial cleaning services near me | 27,100 | Local intent without a place name |
| office cleaning services | 18,100 | Business-to-business wording |
| commercial cleaning and janitorial services | 18,100 | Both labels in one phrase |
| janitorial services near me | 9,900 | Local intent |
| commercial cleaning services chicago | 5,400 | City term |
| commercial janitorial services chicago | 5,400 | City term plus both labels |
| chicago commercial cleaning services | 2,900 | Re-ordered city variant |
| commercial cleaning services nyc | 1,000 | Shows a smaller city market |
Source for all rows: OpenRush keyword research, 20 October 2026 [24].
The key difference from the UK is vocabulary. Two labels, “commercial cleaning” and “janitorial”, carry large volumes, and both phrases are often used together. A site written with only one would miss part of the audience. The US data also includes specialist demand, for example “hospital janitorial services” at 5,400 and “post construction cleaning” at 14,800 [24]. I read these as separate sub-topics, each of which could be its own page, not as variants of the main service.
What the live results show. On 20 October 2026, the top results for “janitorial services chicago” from Chicago included independent local firms, national franchise systems such as Vanguard and Jani-King, a large national maintenance provider, and Yelp’s directory page. There was a local pack of three businesses with between 7 and 64 reviews, and no AI Overview [13]. People also ask included “What is the difference between cleaning and janitorial services?” and “How much do cleaning services typically cost in Chicago?” [13]. One local firm’s snippet named suburbs it serves, including Oak Brook, Schaumburg and Rosemont [13]. This shows how suburb names appear in local copy.
The map for Prairie Line.
| Cluster | Page | Primary question | Intent |
|---|---|---|---|
| Hub | Janitorial and commercial cleaning in Chicago | What is included in a janitorial contract? | Commercial |
| Definitions | Cleaning versus janitorial services | What is the difference? | Informational |
| Services | Office janitorial; day porter service; floor care; restroom care | What do I get, and how often? | Commercial |
| Specialist | Medical facilities; schools; restaurants; post-construction | What does my building type need? | Commercial |
| Pricing | What commercial cleaning costs in Chicago | How much, and what changes the price? | Commercial investigation |
| Trust | Insurance, training and standards | Can I rely on this contractor? | Commercial investigation |
| Areas | Chicago neighbourhoods and the suburbs served | Do you cover my building? | Local |
The “Definitions” cluster comes straight from the live “People also ask” box [13]. In the UK example it is not needed, because UK searchers tend to use one label. That is the biggest structural difference between the two maps.
Publishing order. Hub, then the definition page (it is short, answers a question people actually ask, and every other page can link to it), then services, specialist pages, pricing, trust, areas.
Local signals for the US example. A Google Business Profile, consistent name, address and phone number across the site and directories such as Yelp, which appears in the results [13], and named suburbs and neighbourhoods the business really serves. For credentials, ISSA, a cleaning industry association, runs the Cleaning Industry Management Standard, which it describes as a certification for “quality-driven building service contractors and in-house cleaning organizations” [28]. A real certification is a verifiable claim. An unearned one would be worse than none.
Internal links between the pages
A map is only half a plan. The links turn separate pages into a connected set. Google recommends linking to related pages in context, and says anchor text should be “descriptive, reasonably concise, and relevant” [26]. It also says every page you care about should be linked from at least one other page on the site [26].
For each example, I would write links inside the body text, where the surrounding sentence explains why the reader would want the next page, and I would vary the anchor wording. For the London pricing page, links to the services pages might read “what a daily clean covers”, “our deep clean checklist” or “washroom and kitchen cleaning”. Each describes the target without repeating one phrase everywhere. The same idea applies in Chicago: one link might say “day porter service”, another “restroom care between scheduled visits”.
I give the principles of internal linking in depth in my content architecture guide.
What differs between the two markets
| Aspect | London example | Chicago example |
|---|---|---|
| Main service label | Office cleaning, commercial cleaning | Janitorial services, commercial cleaning, often together |
| Spelling and style | British English; “organisation”, “programme” | American English; “organization”, “program” |
| Company form | Ltd | LLC |
| Estimated volume, broad head term | “commercial cleaning services”: 1,900 [24] | “commercial cleaning services”: 90,500 [24] |
| Estimated volume, city term | “commercial cleaning services london”: 1,300 [24] | “commercial cleaning services chicago”: 5,400 [24] |
| Directory in the results | Checkatrade [13] | Yelp [13] |
| Competitor types | Independent firms | Independent firms plus national franchise systems [13] |
| Trust signals competitors state | Vetted, DBS checked, COSHH compliant [13] | Franchise network, years in business, service area [13] |
| Industry body | BICSc [29] | ISSA, CIMS [28] |
| Extra vocabulary work | Little | A definitions page for cleaning versus janitorial |
| Local naming | Boroughs, areas and postcodes | Neighbourhoods and suburbs |
The head-term figures show the scale gap. “Commercial cleaning services” has about 48 times more estimated monthly searches in the US than in the UK in this data [24]. I calculated that ratio from the two estimates. I did not take it from any source, and I would not rely on it beyond showing that the markets differ in size.
What these examples cannot tell you
They use estimated volumes, single snapshots and invented businesses. They do not tell you how long a real site would take to rank, or whether it would. The map is a hypothesis about what a site should publish, and Search Console, by country and cluster, is how you find out whether it was right.
Content architecture, silos and structured data: the short version
This section gives the idea and shows where it fits in the method. For the full treatment, including URL rules, linking patterns and example markup, see my content architecture guide.
Content architecture
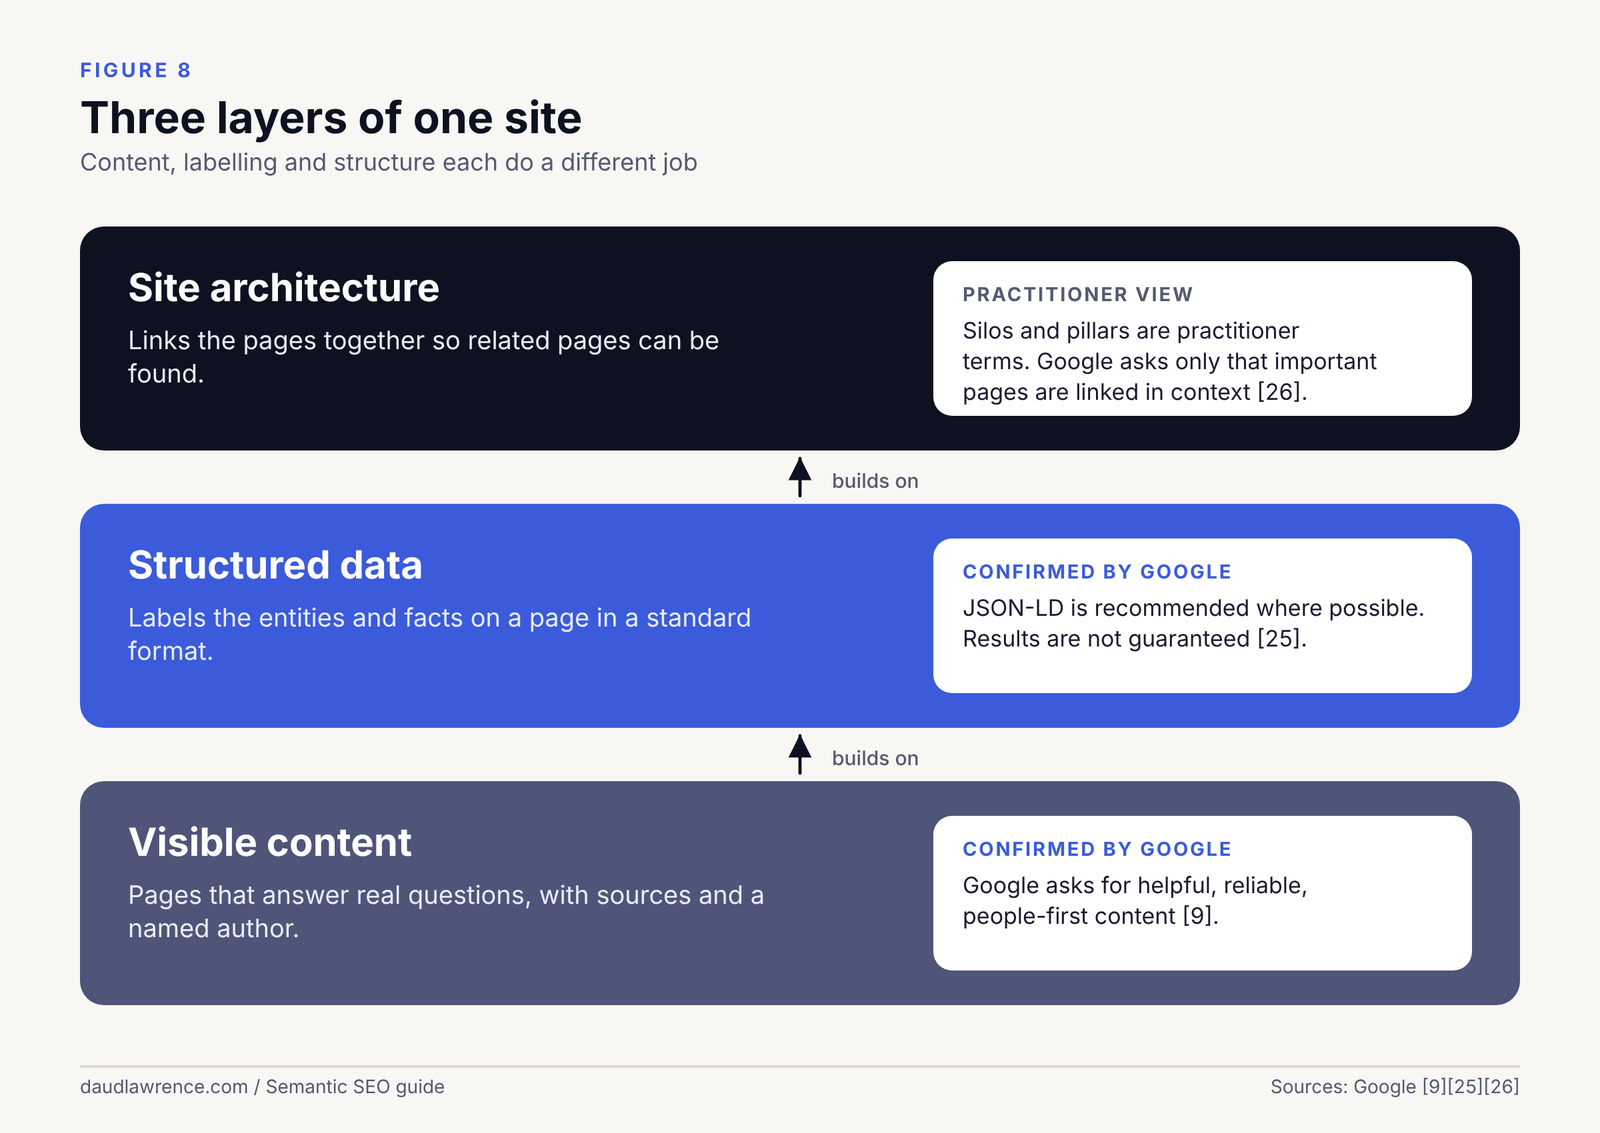
Content architecture is how pages are organised and connected. A common pattern is the pillar and cluster model: a broad page (the pillar) covers a subject in general, and supporting pages (the cluster) cover narrower questions and link back to it. A silo is a group of pages on one theme, linked mainly to each other, so the structure of the site mirrors the structure of the subject.
These are practitioner terms. Google does not require silos or pillars. Its guidance says only that every page you care about should be linked from another page, and that links should sit in context with descriptive anchor text [26]. A clear structure helps people and crawlers find related pages. That makes it a sensible choice, but not a proven ranking factor.
In the four-stage method, architecture is the second stage: after you know the entity landscape, you decide which pages exist and how they connect.
Structured data
Structured data is code on a page that labels its content in a standard format. Google describes it as “a standardized format for providing information about a page and classifying the page content” and recommends JSON-LD where a site allows it [25]. It also uses hedged language: structured data “can enable” rich results, and nothing is guaranteed [25].
Three points matter for semantic SEO.
- It states facts, it does not create authority. Markup that says who you are, what you do and where you are makes your side of the exchange clearer. It does not make a thin page strong.
- It must match the visible page. Markup describing things a reader cannot see is a risk.
- Check what is still supported. Google’s FAQ markup documentation records that the FAQ rich result “will no longer appear in Google Search starting May 7, 2026” [23]. Google also announced changes to HowTo and FAQ rich results in August 2023 [30]. Advice written before those dates may be out of date. The FAQ questions on a page are still useful to readers, whatever happens to the markup.
For a local business like either example above, the relevant type is LocalBusiness. Google lists name and address as required properties, and treats others, such as opening hours and telephone, as recommended [27]. On AI features, Google says no special markup is needed [2].
Where this fits in the method
Architecture sets the shape of the site. Structured data labels the entities on it. Neither replaces the content. Both are covered properly in my content architecture guide.
Writing semantically: how to make a page clear to people and to search systems
Start with the question, not the keyword
A semantic page has one main job. Before I write, I put the page’s primary question into a sentence, for example “How is office cleaning priced in London, and what should a quote include?” If I cannot say what the page answers in one sentence, the page is probably two pages.
This matches how Google describes the goal. Its guidance for creating helpful content asks whether the content provides “original information, reporting, research, or analysis” and “a substantial, complete, or comprehensive description of the topic” [9]. It also asks whether a reader will leave feeling they have “learned enough about a topic to help achieve their goal”, and suggests evaluating content by who created it, how and why [9]. A page built around a question makes those tests easy to apply.
Principles I follow
Answer first, then explain. I put the direct answer in the first paragraph, and use the rest of the page for detail, evidence and exceptions. Google has said it can rank individual passages, not only whole pages, for some queries [6]. That makes a clear, self-contained section more useful than a long run-up. This is Confirmed by Google for passage ranking, and Practitioner view for the writing advice that follows from it.
Use one name for one thing. If a page says “janitorial services” in one paragraph and “custodial contractors” in the next, a reader may wonder whether they are different. Pick the main label, state the alternatives once (“also called commercial cleaning in the UK”) and then stay consistent. This is the page-level version of entity reconciliation, and it is an inference.
State the attributes people need. For a service, those are usually what is included, how often, how long, who does the work, what it costs and what could change the cost. For a person or business, they are the name, location, role and verifiable credentials. A page that leaves them out forces the reader to search again.
Define terms once, plainly. The first time a technical word appears, explain it in the same sentence. This helps beginners, and it also makes each section easier to understand when read alone.
Give a specific that others do not. A page that repeats what the top ten already say adds nothing. Add a real number, a worked example, a checklist from experience or a photograph. I call this the information gain question: after reading this page, what does the reader know that they would not have learned from the others? That term is a practitioner term, not a Google metric.
Keep claims checkable. Name the source, the date and, where relevant, the author. Google’s guidance repeatedly points to trust as the most important quality [9].
What I avoid
- Stuffing a page with related terms in the hope of matching a hidden list. There is no confirmed list, and I explain why in the myths section.
- Repeating the same phrase in every heading. Google’s title guidance warns against keyword stuffing and says to be descriptive and concise [33].
- Writing a separate page for every spelling or word-order variant. They share intent, so they belong on one page.
A before-and-after example
The example uses the fictional London business from the topical map section. The text is illustrative.
Before: “We offer the best office cleaning services in London at affordable prices. Our office cleaning prices are competitive and our office cleaners are professional. Contact us for office cleaning prices today.”
This repeats a phrase, claims quality without evidence, and answers nothing.
After: “Office cleaning in London is usually priced by the number of hours, the size and layout of the space, and how often the cleaners visit. A quote should state the hours per visit, the days, what is included, who supplies materials and equipment, and how the contract can be ended. This page explains each part so you can compare quotes on the same basis.”
The second version answers the question in the first sentence, lists the attributes a reader needs, and tells the reader what the page will do.
Title, description and heading for a page
Every page needs a title, a description and a main heading. Google says each page should have a title element that is unique, descriptive and concise, and that titles can be shortened in results [33]. Google may also rewrite a title link when it does not reflect the page, using the title element, the main visible title, headings and anchor text [33]. So the title, the H1 and the first paragraph should agree. The page I read does not give guidance on meta descriptions, so what follows about them is a practitioner view.
| Page | Title (under 60 characters) | Meta description (under 155 characters) | H1 |
|---|---|---|---|
| London pricing page (fictional) | Office cleaning prices in London: what sets the cost | How office cleaning is priced in London, what a quote should include and the questions to ask before signing a contract. | Office cleaning prices in London |
| Chicago definitions page (fictional) | Cleaning vs janitorial services: the difference | What janitorial services include, how they differ from general cleaning, and what to check in a commercial cleaning contract. | What is the difference between cleaning and janitorial services? |
AI search: what Google says and what is still guesswork
The facts Google has published
Google’s guidance on AI features, last updated on 10 December 2025, makes five points that matter here [2].
- A page is eligible to appear as a supporting link in AI Overviews and AI Mode if it is “indexed and eligible to be shown in Google Search with a snippet”, and there are no additional technical requirements [2].
- Indexing and serving are not guaranteed, even if the requirements are met [2].
- There is no special schema.org markup needed, and no new machine-readable files [2].
- Both features may use query fan-out, which Google describes as “issuing multiple related searches across subtopics and data sources” [2]. Elizabeth Reid described the same technique in May 2025 [17].
- Visits from AI features are counted in overall search traffic and reported in the Performance report under the Web search type [2].
Google also lists standard practices: allow crawling, make important content available as text, keep structured data consistent with the visible text, and keep Business Profile information current where it applies [2].
What this means for semantic SEO
Because there is nothing special to add, the practical question is how to be a good source when a question is broken into parts. This is where the earlier sections help, and it is an inference, not a Google instruction.
- A site that covers the likely sub-questions of a topic gives a system more passages to choose from.
- Clear definitions and consistent names reduce the chance of a passage being misread.
- Verifiable authorship and sources match what Google asks for in its helpful content guidance [9].
What I cannot tell you
I cannot tell you which sources Google chooses for a given AI answer, how often a page is shown, or how to guarantee a mention. Many articles describe tactics for “generative engine optimisation”. I have found no Google statement that confirms any of them beyond what is listed above. Treat them as practitioner views and test them.
Measurement is also limited. The page I read says AI feature traffic appears inside the Web performance report [2]. It does not describe a separate report for it. So if you cannot isolate AI traffic in Search Console, that is a reporting limit, not a mistake in your setup.
What the live results showed
On 20 October 2026, an AI Overview appeared for “semantic seo” from both the US and London [13]. It did not appear for “office cleaning london” or “janitorial services chicago”, where the results were company websites, directories and a local pack [13]. This is one snapshot and I do not draw a general rule from it. It does suggest that local commercial queries often lean on the local pack, so I check what appears for each market before assuming AI answers matter to a given page.
Semantic SEO for local service businesses in the US and UK
Why local businesses need their own approach
A local service business is judged on more than its pages. Google’s guidance for Business Profiles says local results are based mainly on three factors: relevance, distance and prominence [32]. It defines relevance as “how well a Business Profile matches what someone is searching for”, distance as “how far each business is from the customer who’s searching”, and prominence as “how well-known a business is” [32]. It adds that prominence is also based on information such as the number of reviews, and that more reviews and positive ratings can help local ranking [32].
That has two consequences. Distance is something you cannot change with copy. And the other two depend partly on things outside your website, which is why off-site signals are one of the four stages in my method.
One service, many names
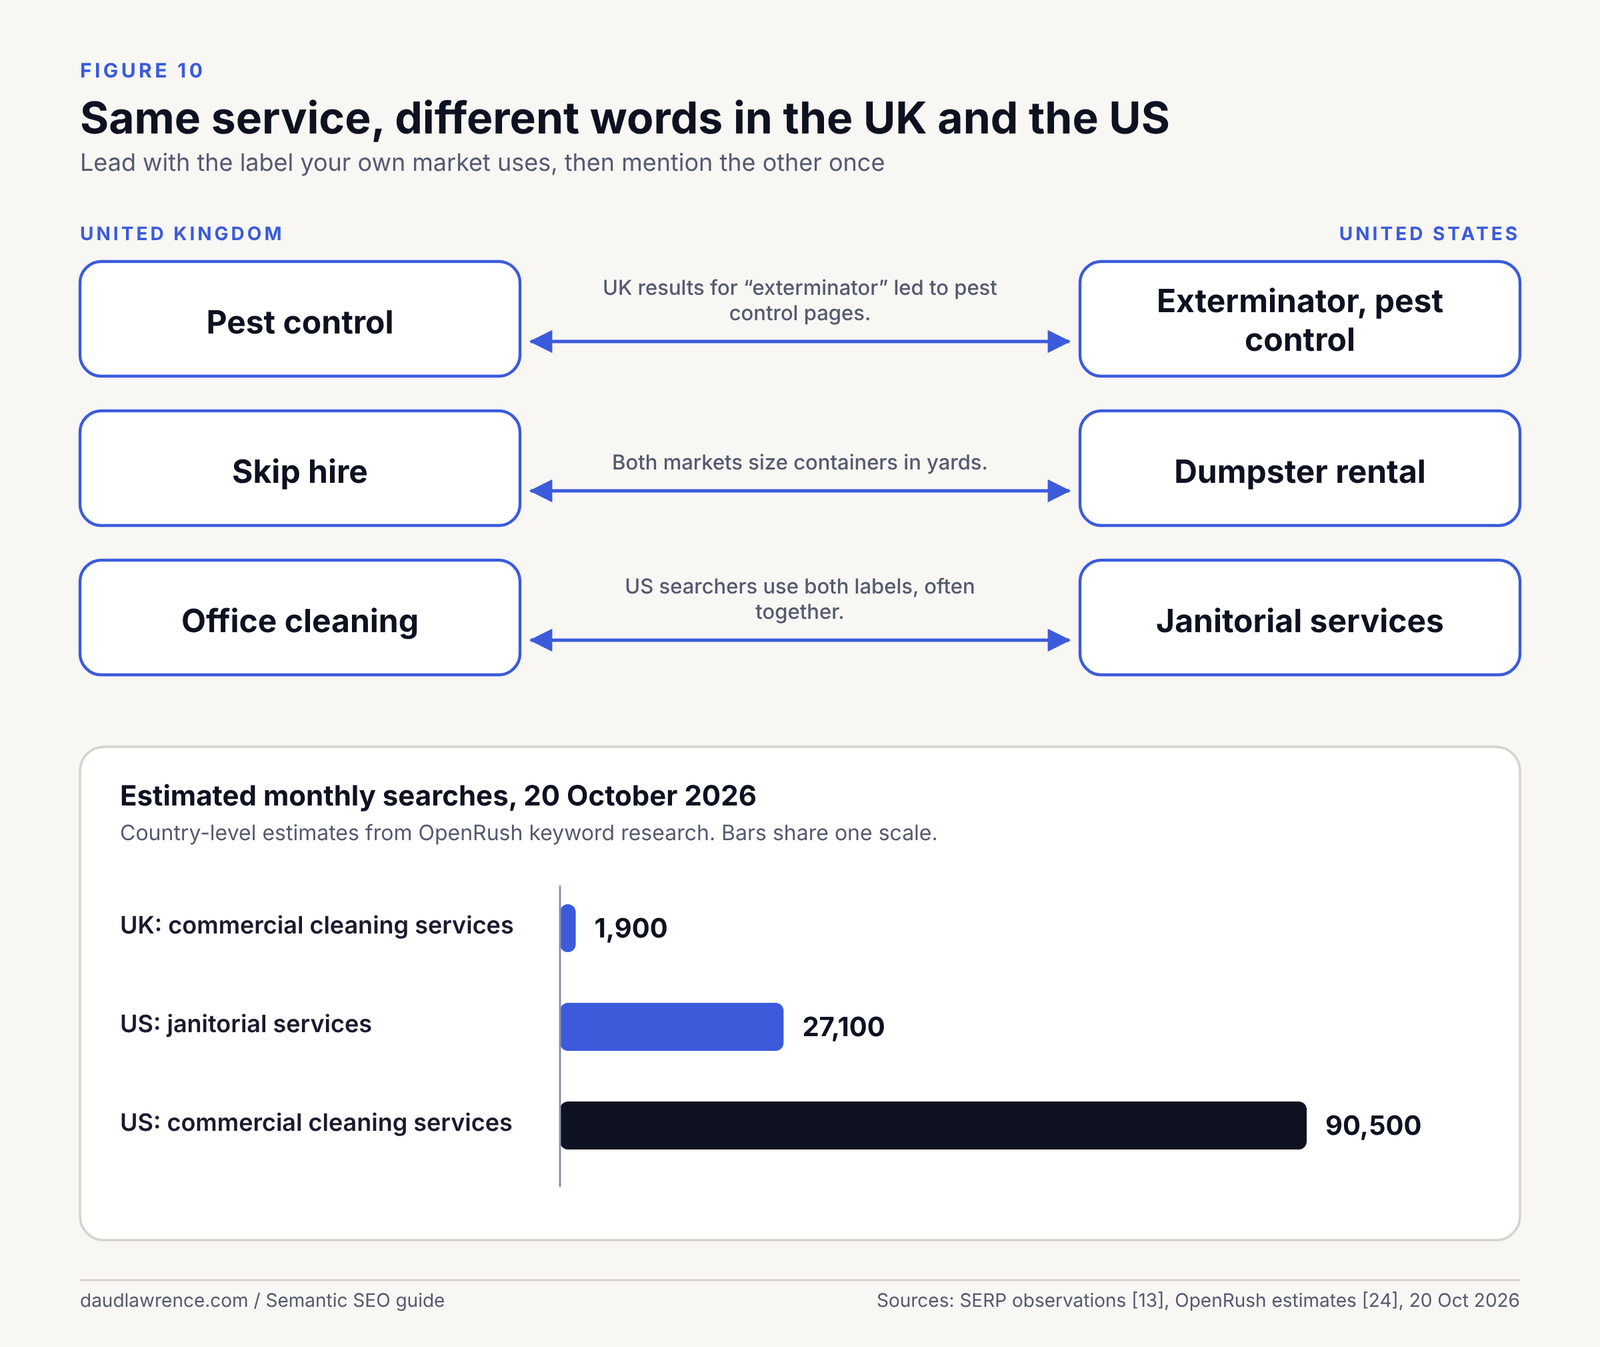
The same service has different names in different markets, and sometimes more than one within the same market. The table below uses my SERP observations from 20 October 2026 [13].
| UK term | US term | What I saw |
|---|---|---|
| Pest control | Exterminator, pest control | The UK results for “exterminator” included a government page titled for pest control and a question asking the difference between the two words. The US results for “pest control” included national brands and public health pages [13] |
| Skip hire | Dumpster rental | Both markets size containers in yards. The questions asked differed in wording [13] |
| Office cleaning | Janitorial services | The live results for “office cleaning services” and “janitorial services” show different mixes of directories and companies [13]. Keyword data shows large volumes for both US labels [24] |
The lesson is not that one label is right. It is that a local business should find out which labels its own market uses, state the main one in titles and headings, and mention the other where a reader might use it.
Location pages
Many local sites publish one page for every town, changing only the place name. I advise against it. That is a practitioner view: such pages add little for the reader, they are cheap to copy, and they are hard to keep accurate. A better test is whether a location page contains something specific to that place, such as the actual service area, local examples, named neighbourhoods or suburbs the business really serves, or reviews from clients there. In my Chicago observation, one competitor’s snippet named the suburbs it serves, which is the kind of detail a location page can carry [13].
Credentials and trade bodies
Credentials are verifiable relationships with organisations outside your site. I only list those I have been able to check, and only if the business can truthfully claim them.
- United Kingdom: The British Institute of Cleaning Science, BICSc, describes itself as “the largest independent, professional and educational body within the cleaning industry” and offers membership and accredited training [29].
- United States: ISSA runs the Cleaning Industry Management Standard, a certification for building service contractors and in-house cleaning organisations [28].
I have not verified trade bodies for pest control or skip hire, so I do not name any here. That belongs to a future article.
Directories and listings
The results I looked at gave local searchers directories as well as company sites. In London, Checkatrade appeared in the results for office cleaning. In Chicago, Yelp did [13]. A listing is a place where your name, address and phone number appear, so each one should match your website. That consistency is a practitioner view. Google’s Business Profile guidance is the confirmed part: keep your information accurate and encourage reviews [32].
The method: four stages from research to authority
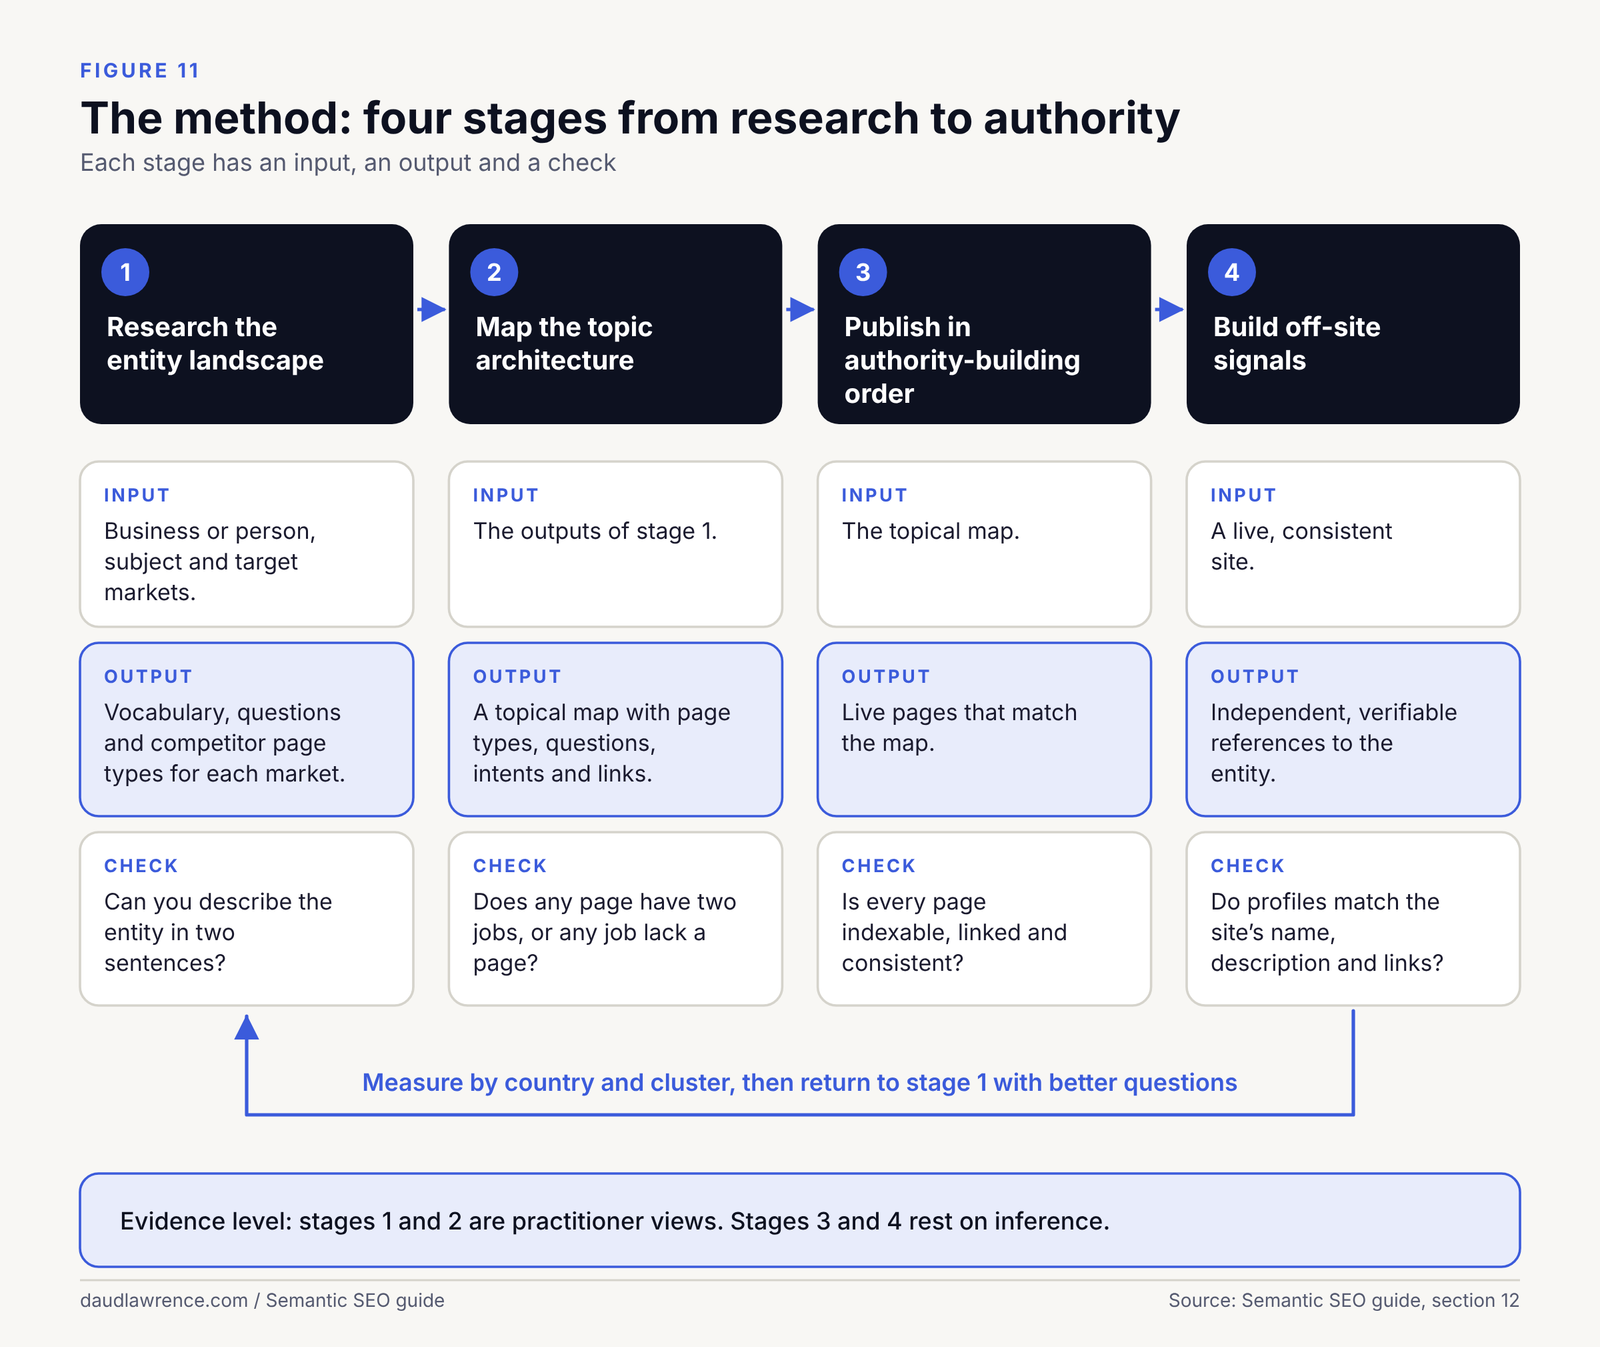
I use four stages in order. Each one has an input, a set of actions, an output and a check. The labels are plain on purpose.
Stage 1: research the entity landscape
Input: the business or person, the subject and the target markets.
Actions: – Write down the central entity and its attributes: name, type, place, services, people, credentials. – Collect the names people use for the service in each market, using live results and keyword data. – Collect the questions asked, from “People also ask” and related searches. – Note who ranks and what types of page they are.
Output: a vocabulary list, a question list and a competitor page-type list, per market.
Check: can you describe the central entity in two sentences, and does the vocabulary list show where the markets differ?
Stage 2: map the topic architecture
Input: the outputs of stage 1.
Actions: – Group questions by intent. – Assign one page to each group and name its primary question. – Draw the hierarchy: hub, services or guides, supporting questions. – Plan the contextual links between pages and vary the anchor wording.
Output: a topical map with page types, questions, intents and links.
Check: does any page have two jobs, or any job lack a page? I cover this stage more fully in my content architecture guide.
Stage 3: publish in authority-building order
Input: the topical map.
Actions: – Publish the hub and the central entity pages first, so every later page has something to link to. – Publish core pages next, then supporting questions, then local and secondary pages. – Add structured data that matches the visible page. – Link new pages to older ones in context.
Output: live pages that match the map.
Check: is every page indexable, linked from another page, and consistent with the others in names and facts? Google’s own advice is that every page you care about should be linked from at least one other page [26].
The order is an inference from how pages depend on each other. Google has not said that publishing order affects rankings.
Stage 4: build off-site signals
Input: a live, consistent site.
Actions: – Keep business profiles and directory listings accurate and consistent with the site. – Join the organisations the business truly belongs to and cite them correctly. – Earn mentions from real publications and partners by publishing something worth citing. – Link your own profiles to your site and back.
Output: independent, verifiable references to the entity.
Check: do the profiles use the same name, description and links as the site?
This stage rests on inference. The Knowledge Graph originally drew on sources including Wikipedia and the CIA World Factbook [1], and Google’s local ranking guidance counts prominence [32]. Beyond that, the claim that off-site mentions help a system reconcile an entity is a practitioner view and an inference. It is how I work, and I measure rather than assume.
How the stages fit together
The stages repeat. Measurement after stage 4 shows which clusters gained and which did not, and sends you back to stage 1 with better questions. I describe measurement in the next section.
| Stage | Main output | Evidence level for the practice |
|---|---|---|
| 1. Research the entity landscape | Vocabulary, questions, competitor page types | Practitioner view, supported by live results |
| 2. Map the topic architecture | Topical map and link plan | Practitioner view, with Google guidance on links [26] |
| 3. Publish in authority-building order | Live, consistent pages | Inference |
| 4. Build off-site signals | Consistent profiles and independent mentions | Inference and practitioner view |
Measuring semantic SEO: a Search Console and GA4 plan
Treat each plan as a hypothesis
Because so much of semantic SEO rests on inference, I measure it as a series of testable statements. A good hypothesis names the change, the metric, the market, the time window and the baseline. For example:
If I publish the six missing supporting pages in the pricing cluster, then impressions for that cluster’s queries from UK users will be higher after twelve weeks than in the twelve weeks before, measured in Search Console.
If the number does not move, the hypothesis failed. That is still useful. It tells me to look at indexing, intent or quality before publishing more.
What Search Console can tell you
Google’s Performance report shows four main metrics. Clicks are the times a user clicked your site from Google Search results. Impressions are how many times your site appeared in Search results. CTR is clicks divided by impressions. Average position is “the average position of the topmost result from your site” [34]. The report can be split by queries, pages, countries, devices, search appearance and dates, and filtered by search type, including Web [34].
The country dimension is what makes the US and UK comparison possible. The page dimension, filtered by a URL folder, is what makes cluster measurement possible. The default view covers the past three months, and recent data is preliminary and may change within hours [34]. The page I read does not state a maximum history, so I export the data on a schedule and keep my own copy. That last step is my own habit, not a Google instruction.
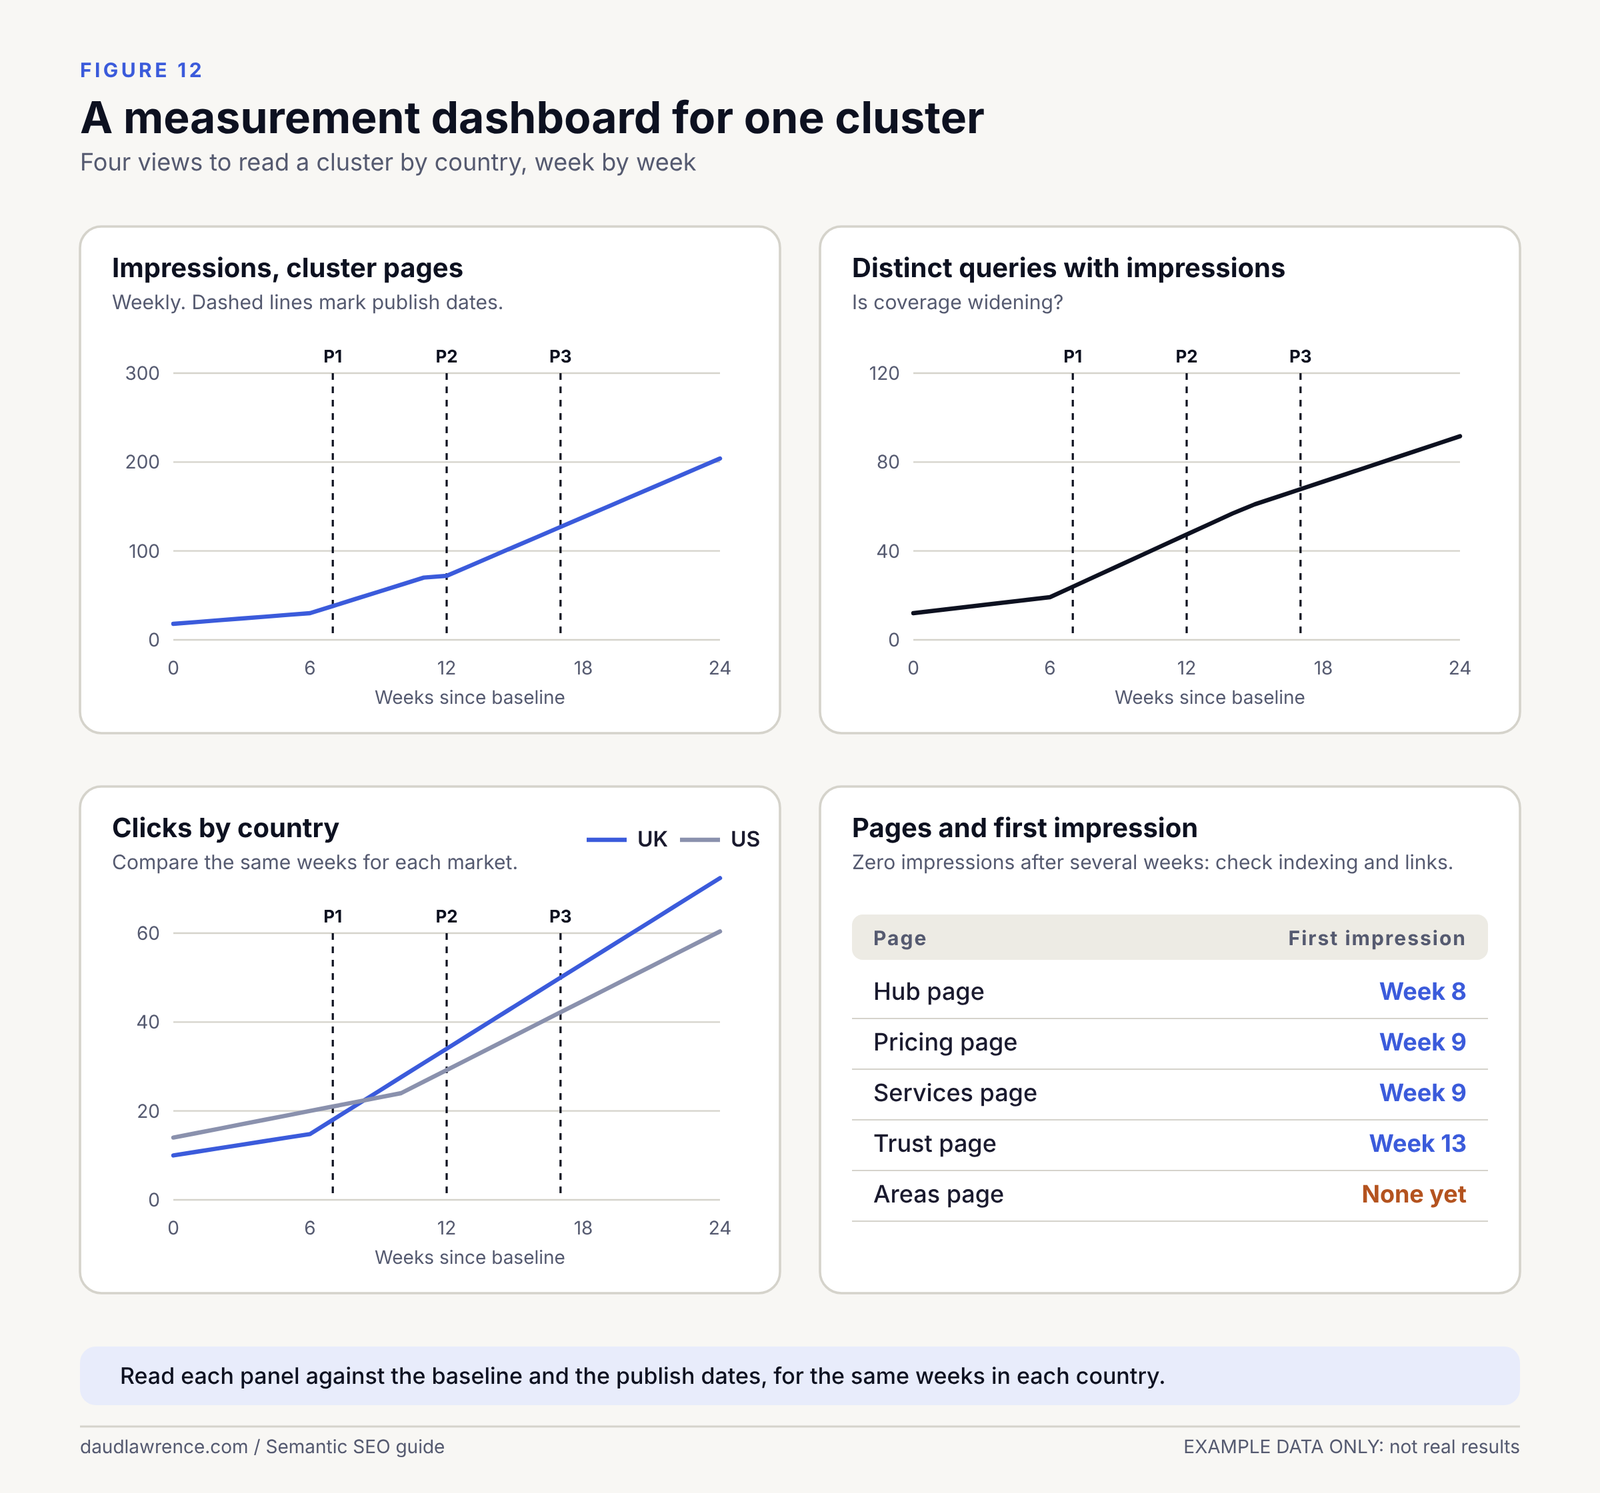
A cluster-level scorecard
| Measure | Where | What it tells you | Caution |
|---|---|---|---|
| Impressions by cluster | Search Console, pages filtered by URL folder | Whether the cluster is being shown at all | Impressions can rise without clicks |
| Distinct queries by cluster | Search Console, queries tab | Whether coverage is widening | Count queries with at least one impression, and note the date range |
| Clicks by country | Search Console, countries tab | Whether the US and UK each respond | Compare like with like, for the same weeks |
| Average position | Search Console | Direction of travel | It averages the topmost result per query and can fall when you gain many new low-ranking queries [34] |
| Pages with impressions | Search Console, pages tab | Whether new pages are discovered and shown | A page with zero impressions after several weeks needs a check on indexing and links |
| Branded query impressions | Search Console, queries filtered by name | Whether the entity is being recognised | An inference, not a confirmed signal |
| Organic sessions and key events | GA4 | What visitors do after arriving | See the note below |
What GA4 can tell you
Google Analytics 4 groups visits into channels. Its Organic Search channel covers non-ad links in organic search results, and Google states that this includes AI Overviews and AI Mode [35]. So GA4 cannot separate AI-feature visits from ordinary search either. Use GA4 for what visitors do next, such as which pages they view and which key events they complete, and use Search Console for how you appear.
A simple routine
- Baseline. Before publishing, export the last three months of data for the cluster, split by country.
- Annotate. Record the publish date of each page.
- Wait. I use twelve weeks as a working window for small sites. That figure is my own default, not a Google statement, and the right window depends on how often a site is crawled.
- Compare. Look at the same weeks before and after, by country, for the cluster only.
- Check for confounds. Did a core update, a seasonal change or a site change happen at the same time?
- Decide. Keep, change or drop the hypothesis, and write down why.
Myths and mistakes in semantic SEO advice
I list each claim, what the evidence says and how confident I am. Where I say “I have not found”, I mean that I looked and could not find a Google statement. It does not prove that none exists.
| Claim | What the evidence says | Status |
|---|---|---|
| “You need LSI keywords.” | John Mueller of Google wrote in July 2019 that there is “no such thing as LSI keywords” [36]. The term comes from an old information retrieval technique, and I have found no Google documentation that uses it | Myth |
| “Semantic SEO means adding schema.” | Google says structured data “can enable” rich results and nothing is guaranteed [25]. It is one way to state facts, not the method | Misleading |
| “Add FAQ and HowTo markup for rich results.” | Google’s FAQ documentation says the FAQ rich result “will no longer appear in Google Search starting May 7, 2026” [23]. Google announced changes to both features in August 2023 [30] | Out of date |
| “Topical authority is a confirmed ranking factor.” | I have found no Google document for it. John Mueller replied “Don’t worry about it” to a thread on the term, according to one report [15] | Unproven |
| “E-E-A-T is a ranking factor.” | Google says it “isn’t a specific ranking factor” and that trust is the most important part [9] | Myth as stated |
| “Mention more entities and you rank higher.” | The patents I read describe weighting by entity type and scoring related entities, not entity counts per page [18][19][20] | Unproven |
| “AI Overviews need special optimisation.” | Google says there are no additional requirements, and no special schema [2] | Myth |
| “Google’s patents describe what it does today.” | A patent shows what was filed. I read no claims, and one of the four concerns video [21] | Unsafe |
| “NLP tool scores predict rankings.” | These tools can show how a model labels your text. I have found no Google statement that such scores are used in ranking | Unproven |
| “Semantic SEO replaces keywords.” | Google said in 2013 that pages matching meaning should do better, and that its advice to publishers had not changed [3] | Myth |
The pattern behind the myths
Most of these start with something true and stretch it. Google does use language models [5][6]. Structured data does help Google understand a page [25]. Topic coverage does make sense for readers. The stretch is the claim that a specific tactic produces a specific ranking result. When I see such a claim, I ask for the source, the date and whether it was a test or an opinion.
A semantic SEO checklist
Use this as a review before and after publishing. Each item links back to a section above.
Entity and vocabulary – The central entity is described in two sentences, with name, type, place and verifiable credentials. – The main label for the service is chosen per market, and the alternatives are mentioned once. – Names, facts and figures match across every page and profile.
Intent and structure – Each page has one primary question and one intent, checked against the live results in the target country. – The topical map shows no page with two jobs and no job without a page. – Every page you care about is linked from at least one other page, in context, with descriptive anchor text [26].
Page quality – The answer comes first, and terms are defined when they first appear. – At least one specific the top results do not have: a real example, figure or checklist. – Claims have sources, dates and a named author [9]. – Title, H1 and first paragraph agree, and the title is unique, descriptive and concise [33].
Structured data – Markup matches the visible page, and uses JSON-LD where the site allows it [25]. – You have checked that each markup type is still supported before relying on it [23].
Off-site – Profiles and directory listings use the same name, address and description as the site. – Credentials are real, current and checkable.
Measurement – A baseline is exported before publishing, split by country. – Each page’s publish date is recorded. – The hypothesis, window and success measure are written down before the change.
Glossary
AI Overview: a Google Search feature that shows a generated summary with links to supporting sites [10].
AI Mode: a Google Search feature that gives a longer generated answer with links, and may use query fan-out [2][17].
Attribute: a fact that describes an entity, such as a business’s address or opening hours.
Co-citation: two documents are related because a third cites both [12].
Co-occurrence: two terms or entities appear close together in text.
E-E-A-T: experience, expertise, authoritativeness and trustworthiness, the qualities Google’s guidance asks content to show. Google says it is not a specific ranking factor [9].
Entity: a distinct thing that can be identified and described, such as a person, organisation, place or product.
Entity reconciliation: deciding that different mentions refer to the same entity.
Information gain: a practitioner term for what a page adds that other pages on the topic do not.
JSON-LD: a format for structured data that Google recommends where a site allows it [25].
Knowledge Graph: Google’s collection of facts about real-world entities and how they relate [1].
Local pack: a group of local business results shown in Google Search, which I saw for both city queries [13].
Passage ranking: Google’s ability to judge a section of a page for some queries [6].
Pillar page: a broad page on a subject that supporting pages link back to.
Query fan-out: the technique of issuing multiple related searches across subtopics to build an AI answer [2].
Relationship: a link between two entities, such as a company being located in a city.
Search intent: the need behind a query, which I infer from the query and the live results [16].
SERP: a search engine results page.
Silo: a group of pages on one theme, linked mainly to each other.
Structured data: code that labels the content of a page in a standard format [25].
Topical authority: a practitioner term for the idea that thorough, consistent coverage of a subject makes a site a stronger source on it. It is not a confirmed Google score [15].
Topical map: a planned list of pages that cover a subject, with the purpose of each and the links between them.
Frequently asked questions
What is semantic SEO in one sentence?
It is the practice of making a site’s meaning clear, by covering a subject through connected pages that state their entities, attributes and answers plainly, so that people and search systems can understand and verify them. It is a practitioner label, not a Google term.
Is semantic SEO the same as entity SEO?
The two terms overlap heavily. Practitioners use “entity SEO” when the focus is on being recognised as a distinct person, business or thing, and “semantic SEO” for the wider practice of covering a topic. Google defines neither.
Do I still need keyword research?
Yes. Words are how people search. Google said in 2013 that its advice to publishers had not changed when it introduced Hummingbird [3]. Keyword research tells you which names and questions your market uses.
Is topical authority a ranking factor?
I have found no Google statement that confirms it as a score or factor. Google’s John Mueller replied “Don’t worry about it” to a thread on the term, according to one report [15]. The practice of covering a topic well is still sensible, and you can test it on your own site.
Do I need schema markup?
It helps state facts clearly, and Google recommends JSON-LD where possible, but it does not guarantee any result [25]. For AI Overviews and AI Mode, Google says no special schema is needed [2].
Should I still add FAQ markup?
Google says the FAQ rich result will no longer appear starting May 7, 2026 [23]. Answering real questions on a page is still useful to readers.
Does semantic SEO help me appear in AI Overviews?
Google says a page is eligible if it is indexed and can be shown with a snippet, with no extra requirements, and that appearance is not guaranteed [2]. Covering the likely sub-questions clearly is a sensible approach, but it is an inference.
How does it differ between the US and the UK?
Vocabulary, scale and the surrounding ecosystem differ. In my 20 October 2026 data, the US uses “janitorial services” alongside “commercial cleaning”, and the UK mainly uses “office cleaning” and “commercial cleaning” [24]. The head term “commercial cleaning services” had about 48 times more estimated monthly searches in the US [24]. Directories and trade bodies also differ [13][28][29].
How long does it take to see results?
I cannot give a reliable timeframe, and Google says indexing and serving are not guaranteed [2]. I set a hypothesis and a window, often twelve weeks for a small site, and measure by country and cluster.
How many pages do I need?
There is no fixed number. The topical map decides: one page for each distinct question or intent, and no more.
Summary
Semantic SEO is a practical way of making a site’s meaning clear. It starts from entities, attributes and questions, not from a list of phrases. It still uses keywords, because words are how people search, but it treats a topic as a connected set of pages, each with one job.
Much of the practice rests on inference. Google has confirmed the Knowledge Graph, language models such as BERT and MUM, passage ranking and query fan-out. It has not confirmed topical authority, entity density or a separate method for AI search. I label the evidence so you can tell which is which.
The US and UK differ in the words people use, the scale of demand and the directories and trade bodies around them. Check the live results in each market before you plan, and do not assume one version of a page serves both.
Plan with a topical map, publish in an order that gives later pages something to link to, build consistent off-site references, and measure by country and cluster in Search Console. Treat every plan as a hypothesis, and be willing to find out it was wrong.
References
Numbers match the bracketed references in the text. All pages were accessed on 20 October 2026 unless stated. Notes in italics say where I could not read the full source.
- Singhal, A. (16 May 2012). Introducing the Knowledge Graph: things, not strings. Google. https://blog.google/products/search/introducing-knowledge-graph-things-not/↩
- Google Search Central. AI features and your website (last updated 10 December 2025). https://developers.google.com/search/docs/appearance/ai-features↩
- KQED (27 September 2013). Google’s new search takes on more complex queries. https://www.kqed.org/news/113079/googles-new-search-takes-on-more-complex-queriesSecondary source for Hummingbird.↩
- The Next Web (26 October 2015). How Google handles search queries it’s never seen before. https://thenextweb.com/google/2015/10/26/how-google-handles-search-queries-its-never-seen-before/Secondary source reporting Bloomberg; the Bloomberg original (https://www.bloomberg.com/news/articles/2015-10-26/google-turning-its-lucrative-web-search-over-to-ai-machines) was not read.↩
- Nayak, P. (25 October 2019). Understanding searches better than ever before. Google. https://blog.google/products/search/search-language-understanding-bert/↩
- Raghavan, P. (15 October 2020). How AI is powering a more helpful Google. Google. https://blog.google/products/search/search-on/↩
- Nayak, P. (18 May 2021). MUM: A new AI milestone for understanding information. Google. https://blog.google/products/search/introducing-mum/↩
- Google Search Central Blog (August 2022). Helpful content update. https://developers.google.com/search/blog/2022/08/helpful-content-updateOnly the title and date could be verified; the body did not load.↩
- Google Search Central. Creating helpful, reliable, people-first content (last updated 5 October 2026). https://developers.google.com/search/docs/fundamentals/creating-helpful-content↩
- Reid, E. (14 May 2024). Generative AI in Search: Let Google do the searching for you. Google. https://blog.google/products/search/generative-ai-google-search-may-2024/↩
- Google for Developers. Knowledge Graph Search API. https://developers.google.com/knowledge-graph↩
- Small, H. (1973). Co-citation in the scientific literature: a new measure of the relationship between two documents. Journal of the American Society for Information Science, 24(4), 265 to 269. https://doi.org/10.1002/asi.4630240406↩
- Lawrence, D. Own observations of live Google results, collected with OpenRush (inspect_serp), 20 October 2026, about 11:50 to 12:12 UTC. Locations: United States (country), London, England, United Kingdom, and Chicago, Illinois, United States. Single snapshot; no outbound link. Country-level US results show listings from many cities.↩
- Google Search Central Blog (March 2024). March 2024 core update and new spam policies. https://developers.google.com/search/blog/2024/03/core-update-spam-policies and PPC Land report with the 5 March 2024 date: https://ppc.land/google-announces-major-search-update-and-new-spam-policiesThe body of the Google post did not load.↩
- Montti, R. (13 November 2023). Google on topical authority: don’t worry about it. Search Engine Journal. https://www.searchenginejournal.com/google-on-topical-authority-dont-worry-about-it/501209/Secondary report of a Reddit comment; the comment is undated in the article.↩
- Google. Search Quality Rater Guidelines (November 2023 version). https://services.google.com/fh/files/misc/hsw-sqrg.pdfA newer version may exist.↩
- Reid, E. (20 May 2025). Google Search AI Mode update. Google. https://blog.google/products/search/google-search-ai-mode-update/↩
- US10235423B2. Ranking search results based on entity metrics. Filed 12 December 2012; granted 19 March 2019. https://patents.google.com/patent/US10235423Claims not read.↩
- US9336311B1. Determining the relevancy of entities. Filed 15 October 2012; granted 10 May 2016. https://patents.google.com/patent/US9336311Claims not read.↩
- US9256682B1. Providing search results based on sorted properties. Filed 5 December 2012; granted 9 February 2016. https://patents.google.com/patent/US9256682Claims not read.↩
- US9213745B1. Methods, systems, and media for ranking content items using topics. Filed 15 March 2013; granted 15 December 2015. https://patents.google.com/patent/US9213745Claims not read; concerns video content.↩
- Google Search Central. How Search works (last updated 18 December 2025). https://developers.google.com/search/docs/fundamentals/how-search-works↩
- Google Search Central. FAQ (FAQPage) structured data, including its change log (last updated 16 October 2026). https://developers.google.com/search/docs/appearance/structured-data/faqpageThe final part of the page was not read.↩
- Lawrence, D. Keyword volume estimates from OpenRush (research_keywords), country level (United Kingdom and United States), 20 October 2026, about 12:10 to 12:11 UTC. Monthly estimates, rounded; no outbound link. ↩
- Google Search Central. Introduction to structured data markup (last updated 10 December 2025). https://developers.google.com/search/docs/appearance/structured-data/intro-structured-data↩
- Google Search Central. Link best practices (last updated 10 December 2025). https://developers.google.com/search/docs/crawling-indexing/links-crawlable↩
- Google Search Central. Local business structured data (last updated 8 September 2026). https://developers.google.com/search/docs/appearance/structured-data/local-business↩
- ISSA. Cleaning Industry Management Standard. https://www.issa.com/cleaning-industry-management-standard↩
- BICSc, the British Institute of Cleaning Science. https://bics.org.uk/↩
- Google Search Central Blog (August 2023). Changes to HowTo and FAQ rich results. https://developers.google.com/search/blog/2023/08/howto-faq-changesOnly the title and date could be verified; the body did not load.↩
- Companies House. Find and update company information. https://find-and-update.company-information.service.gov.uk/↩
- Google Business Profile Help. Tips to improve your local ranking on Google. https://support.google.com/business/answer/7091↩
- Google Search Central. Influencing your title links in search results (last updated 10 December 2025). https://developers.google.com/search/docs/appearance/title-link↩
- Search Console Help. Performance report (Search results): overview and basic setup. https://support.google.com/webmasters/answer/7576553↩
- Analytics Help. Default channel group. https://support.google.com/analytics/answer/9756891↩
- Schwartz, B. (31 July 2019). Google: there is no such thing as LSI keywords. Search Engine Roundtable. https://seroundtable.com/google-lsi-keywords-27970.htmlReports a tweet by John Mueller dated 30 July 2019.↩